
What is FantasyID
FantasyID is a novel identity-preservingvideo generation(IPT2V) framework launched by Alibaba Group and Beijing University of Posts and Telecommunications, which generates high-quality identity-consistent videos based on enhanced facial knowledge. FantasyID is based on Diffusion Transformers and introduces 3D facial geometric priors to ensure the stability and plausibility of facial structures in video synthesis. FantasyID is based on a multi-view face enhancement strategy to prevent the model from simply copying the reference face, increasing the dynamics of facial expressions and head poses. FantasyID is based on a learnable hierarchical perception injection mechanism that selectively injects fused 2D and 3D features into each layer of the diffusion model, balancing identity preservation and motion dynamics.
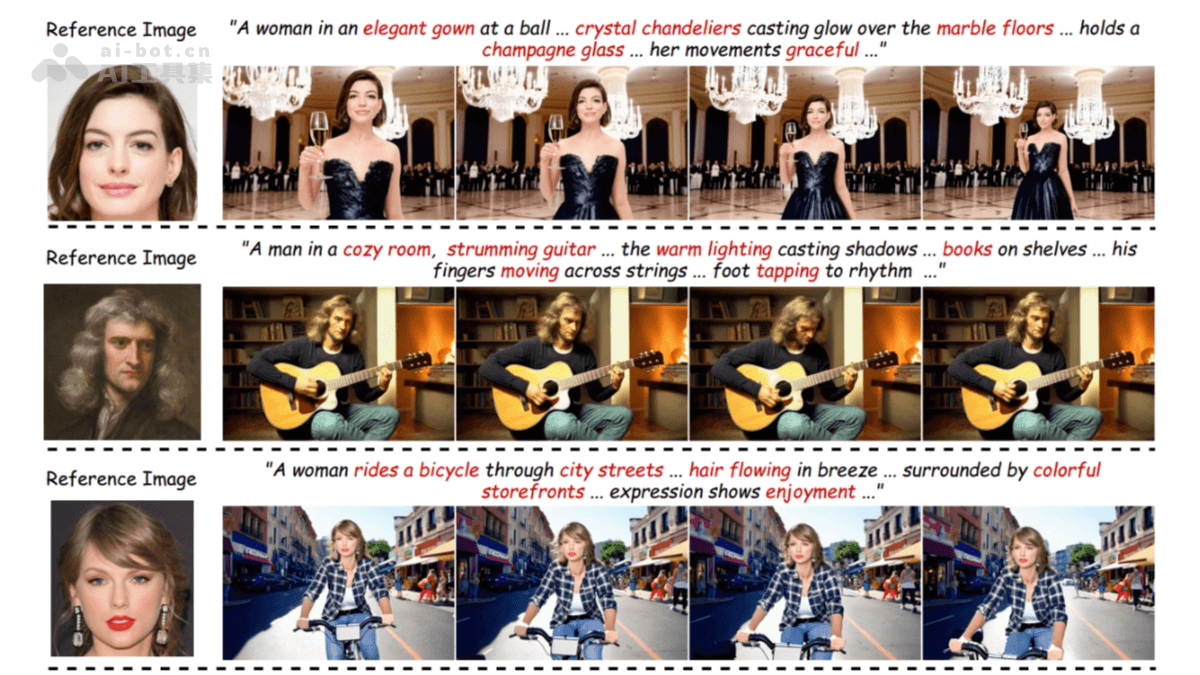
Main Features of FantasyID
- Identity Preservation: Ensures that the facial features of the person in the generated video remain consistent with the input reference image, maintaining a high degree of identity similarity amid complex motion and expression changes.
- Dynamic Enhancement: Increases the diversity of facial expressions and head poses, avoiding the "copy-paste" phenomenon in generated videos.
- High-Quality Video Generation: Combines 3D facial geometric priors and 2D visual features to generate videos with stable structures and rich details while maintaining spatiotemporal coherence of the video.
- No Fine-Tuning Required: Eliminates the need for additional model fine-tuning for each input image, enabling efficient and flexible identity-preserving video generation suitable for large-scale applications.
Technical Principles of FantasyID
- 3D Facial Geometric Priors: Extracts 3D facial structures (such as shape point clouds) from input face images based on the DECA framework, providing stable geometric constraints for video generation and ensuring the stability of facial structures amid dynamic changes.
- Multi-View Face Enhancement: Constructs a multi-view face set, sampling face images from different angles to enhance the model's understanding of 2D facial appearance features, avoiding the monotony of faces in generated videos and improving dynamic expression.
- Feature Fusion: Combines the extracted 2D visual features and 3D geometric features through a fusion transformer to generate comprehensive facial descriptors used to guide video generation.
- Hierarchical Perception Signal Injection: Targeting the hierarchical nature of Diffusion Transformers, a learnable hierarchical perception mechanism is designed to selectively inject fused features into different layers, achieving a balance between identity preservation and dynamic expression.
- Diffusion Model: A generation framework based on diffusion models that reconstructs video content matching text descriptions and identity features from noise through a step-by-step denoising process.
FantasyID Project Address
- Project Website:https://fantasy-amap.github.io/fantasy-id/
- GitHub Repository:https://github.com/Fantasy-AMAP/fantasy-id
- arXiv Technical Paper:https://arxiv.org/pdf/2502.13995
Application Scenarios of FantasyID
- Personalized Virtual Avatars: Used in virtual social networking, the metaverse, and games to generate virtual avatars consistent with user identity.
- Virtual Content Creation: Generates dynamic video content, assisting in film and television, advertising, and short video production, reducing creation costs.
- Virtual Customer Service and Digital Humans: Creates natural and realistic digital human avatars for online customer service and intelligent assistants, enhancing interaction experience.
- Virtual Makeup and Outfit Try-On: Combining e-commerce and the beauty industry, generate dynamic videos for virtual makeup try-on or virtual clothing try-on to optimize the shopping experience.
- Interactive education: Generate dynamic videos of teachers or trainers for online courses and simulated scenarios to enhance teaching effectiveness.