
What is EzAudio
EzAudio is a text-to-audio (Text-to-Audio, T2A) generation model jointly launched by Johns Hopkins University and Tencent AI Lab. Based on an efficient diffusion transformer technology, it is used to generate high-quality audio effects from text prompts. EzAudio's innovation lies in its optimized model architecture and data-efficient training strategy, reaching new standards in generation speed, efficiency, and audio realism. EzAudio introduces classifier-free guidance rescaling technology, simplifying model usage while maintaining audio quality.
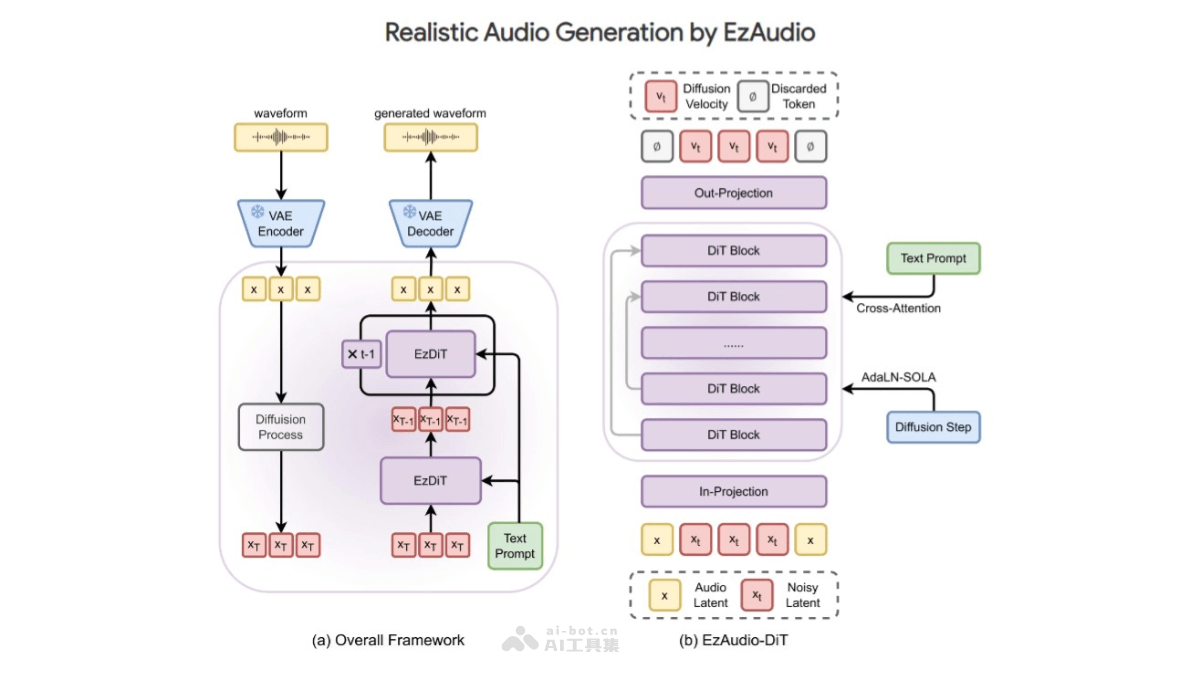
Main features of EzAudio
- Text-to-audio generation: Generate corresponding audio content based on a given text prompt.
- High efficiency: The optimized model architecture reduces the demand for computing resources and improves generation speed.
- High-quality audio: The generated audio has high fidelity, providing a realistic listening experience.
- Data-efficient training: Based on unlabeled data and manually labeled data, it improves training efficiency and model performance.
Technical principles of EzAudio
- Waveform VAE: Based on a one-dimensional waveform variational autoencoder (VAE) to process audio data, avoiding the complexity of processing two-dimensional spectrograms, reducing computational cost while maintaining high temporal resolution.
- Optimized diffusion transformer architecture (EzAudio-DiT): A customized diffusion model, including AdaLN-SOLA and long skip connections, improving the model's parameter and memory efficiency while maintaining training stability.
- Multi-stage training strategy: Combining self-supervised learning and supervised learning, using masked diffusion modeling and synthetic caption data for training, and finally fine-tuning on manually annotated data to improve the accuracy and quality of audio generation.
- Classifier-free guidance rescaling (CFG Rescaling): Adjusting the guidance strength during the diffusion sampling process, optimizing text-to-audio alignment and reducing negative impacts on audio quality.
EzAudio project address
- Project official website:haidog-yaqub.github.io/EzAudio-Page
- GitHub repository:https://github.com/haidog-yaqub/EzAudio
- Technical paper:https://haidog-yaqub.github.io/EzAudio-Page/static/pdf/ezaudio.pdf
Application scenarios of EzAudio
- Music creation: Generate music clips of a specific style or emotion based on text descriptions, assisting musicians and producers in creation.
- Film and television post-production: Generate realistic sound effects and dubbing for movies, TV dramas, or video games, improving the audience's sense of immersion.
- Speech synthesis: Generate speech with standard or specific intonation, used in educational software, audiobooks, or language learning applications.
- Audio editing: Edit and modify existing audio without the need for complex audio editing tools.
- Virtual assistants and chatbots: Generate natural-sounding voice responses for virtual assistants and chatbots.
- Audio content creation: Automatically generate audio for audio blogs, podcasts, or news content.