
What is Enhance-A-Video
Enhance-A-Video is a video generation enhancement algorithm jointly launched by the National University of Singapore, Shanghai Artificial Intelligence Laboratory, and the University of Texas at Austin. The algorithm can significantly improveAI video generationquality, with notable improvements especially in contrast, clarity, and detail realism. The core principle is to optimize the consistency between video frames and visual quality by adjusting the key parameters output by the temporal attention layer.
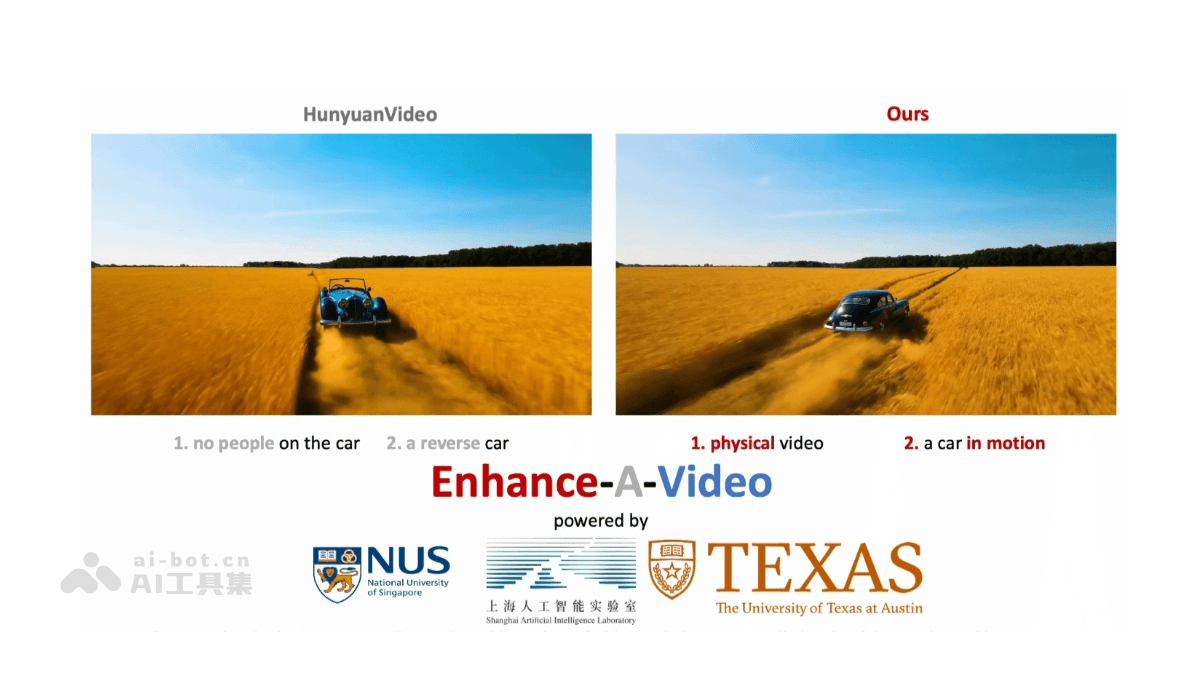
Main features of Enhance-A-Video
- Improve video quality: Enhance-A-Video can significantly improve the contrast, clarity, and detail realism of videos.
- Optimize temporal attention distribution: By adjusting the key parameters output by the temporal attention layer, Enhance-A-Video optimizes the consistency between video frames and visual quality.
- Efficient enhancement: The algorithm can quickly improve video quality without additional performance and memory burden.
- No training required: It can be directly applied to existing video generation models without retraining.
- Plug and play: Enhance-A-Video flexibly adapts to various scenarios and needs, and can be directly integrated into multiple mainstream inference frameworks.
Technical principles of Enhance-A-Video
- Introduction of enhancement coefficient: The algorithm optimizes the distribution of temporal attention by introducing an enhancement coefficient, achieving efficient enhancement, no training required, and plug-and-play.
- Temperature parameter control: Inspired by the pre-softmax Temperature parameter (tau) in LLMs (large language models), the research team discovered for the first time that the Temperature of temporal attention determines the strength of cross-frame correlation, and higher values enable broader attention to temporal context.
- Enhancement block design: An enhancement block was designed as a parallel branch to calculate the average value of off-diagonal elements as cross-frame strength.
- Improvement in detail richness and semantic matching: Enhance-A-Video performs better in detail richness and semantic matching, and the generated video content aligns more closely with the user's input text prompts.
- Deep learning technology: Based on deep learning technology to automatically learn and understand video content, identify and enhance key information in videos such as faces, text, objects, etc., and improve video clarity and detail.
Project address of Enhance-A-Video
- Project official website:https://oahzxl.github.io/Enhance_A_Video/
- Github repository:https://github.com/NUS-HPC-AI-Lab/Enhance-A-Video
Application scenarios of Enhance-A-Video
- Video content creation: Video content creators can use Enhance-A-Video to improve the quality of their works, making videos more realistic and attractive.
- Academic research: Researchers can use Enhance-A-Video to improve the performance of video generation models in academic research and publish high-quality academic papers.
- Online video platforms: Online video platforms can use Enhance-A-Video to improve user experience and provide higher-quality video content.
- Advertising production: Advertising agencies can use Enhance-A-Video to produce promotional videos for new products, simplifying the shooting and post-production process and saving time and cost.
- Film and television special effects: In film and television production, Enhance-A-Video can be used to generate complex scenes, such as space scenes, providing realistic visual effects.