
What is EMO2
EMO2 (End-Effector Guided Audio-Driven Avatar Video Generation) is an audio-driven avatarvideo generationtechnology developed by the Alibaba Intelligent Computing Research Institute, with the full name "End-Effector Guided Audio-Driven Avatar Video Generation". Through audio input and a single static portrait photo, it generates expressive dynamic videos. The core innovation lies in combining audio signals with hand movements and facial expressions, synthesizing video frames through a diffusion model, and generating natural and smooth animations. It includes high-quality visual effects, high-precision audio synchronization, and rich motion diversity.
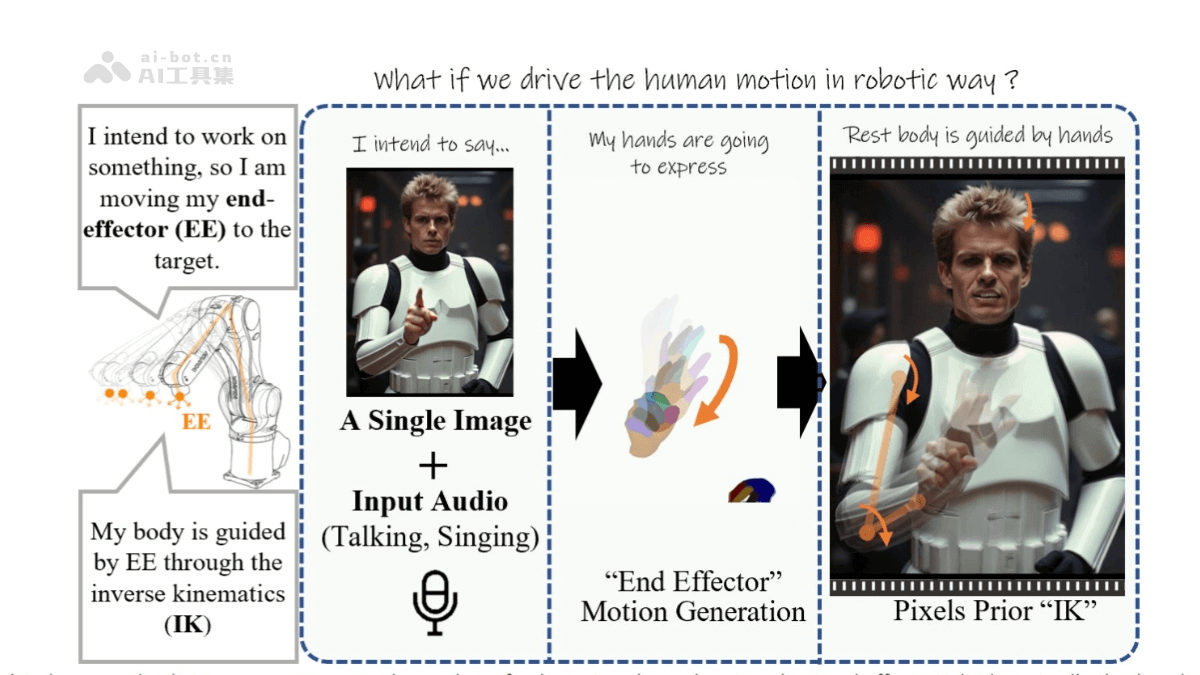
EMO2's Main Features
- Audio-driven dynamic avatar generation: EMO2 can generate expressive dynamic avatar videos through audio input and a single static portrait photo.
- High-quality visual effects: It synthesizes video frames based on a diffusion model and combines hand movements to generate natural and smooth facial expressions and body movements.
- High-precision audio synchronization: It ensures that the generated video is highly synchronized in time with the audio input, improving the overall sense of naturalness.
- Diverse motion generation: It supports complex and smooth hand and body movements, making it suitable for a variety of scenarios.
EMO2's Technical Principles
- Audio-driven motion modeling: EMO2 uses an audio encoder to convert the input audio signal into feature embeddings, capturing the emotion, rhythm, and semantic information in the audio.
- End-effector guidance: This technology pays special attention to the generation of hand movements (end effectors), because there is a strong correlation between hand movements and audio signals. The model first generates hand poses, then incorporates them into the overall video generation process to ensure the naturalness and consistency of the movements.
- Diffusion model and feature fusion: EMO2 uses a diffusion model as its core generation framework. During the diffusion process, the model combines the features of the reference image, audio features, and multi-frame noise, and generates high-quality video frames through repeated denoising operations.
- Frame encoding and decoding: In the frame encoding stage, ReferenceNet extracts facial features from the input static image. These features are combined with audio features and then enter the diffusion process. Finally, the model generates videos with rich expressions and natural movements through decoding.
EMO2's Project Address
- Project official website:https://humanaigc.github.io/emote-portrait-alive-2/
- arXiv technical paper:https://arxiv.org/pdf/2501.10687
EMO2's Application Scenarios
- Virtual reality and animation: It can be used to generate expressive and natural talking-head animations.
- Cross-language and cross-culture: It supports speech input in multiple languages and can generate animations for characters of different styles.
- Role-playing and games: Specified characters can be applied to film and game scenes.