
What is EfficientTAM
EfficientTAM is a lightweight video object segmentation and tracking model launched by Meta AI, capable of solving the high computational complexity problem of the SAM 2 model when deployed on mobile devices. Based on using a simple non-hierarchical Vision Transformer (ViT) as the image encoder, it introduces an efficient memory module to reduce computational complexity, achieving reduced latency and model size while maintaining segmentation quality. EfficientTAM demonstrates performance comparable to SAM 2 on multiple video segmentation benchmarks, with faster processing speed and fewer parameters, making it particularly suitable for video object segmentation applications on mobile devices.
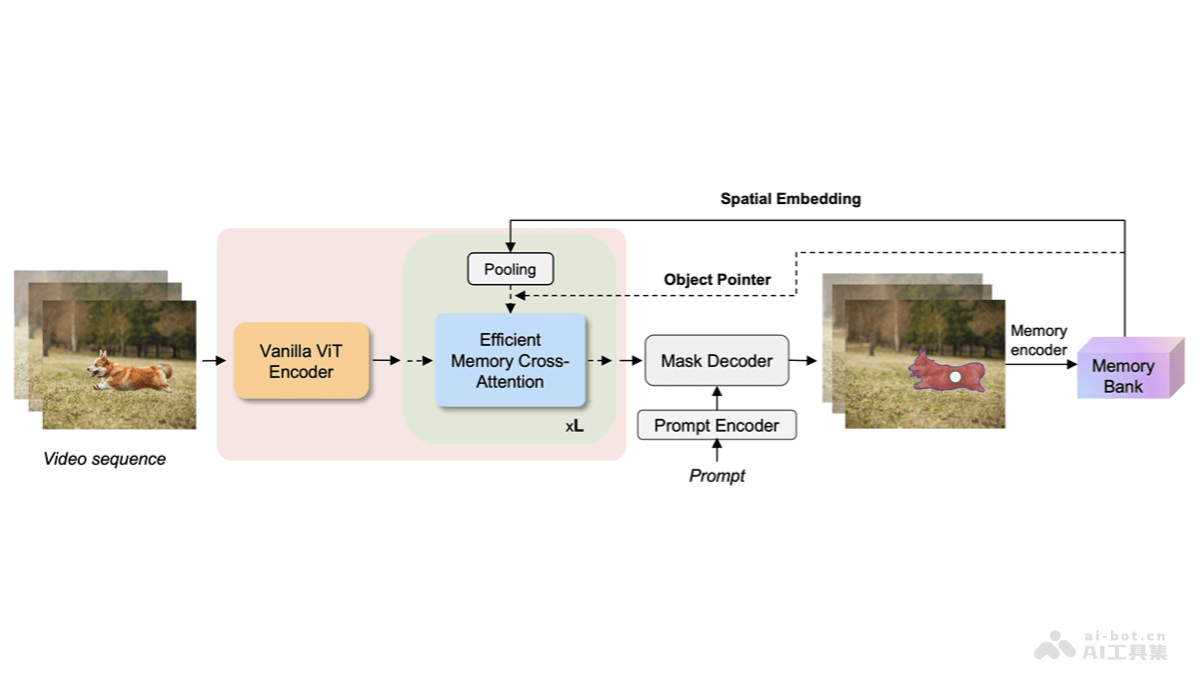
Main Features of EfficientTAM
- Video Object Segmentation: EfficientTAM can segment objects of interest from video frames.
- Track Any Object: The model can track multiple objects in videos.
- Lightweight Design: The model size and computational efficiency are specifically optimized to enable real-time video processing on resource-constrained devices, such as smartphones.
- High-Quality Results: Despite being lightweight, the model can still produce high-quality segmentation results, meeting the needs of high-precision applications.
- Low-Latency Processing: It can perform complex video analysis tasks while maintaining low latency.
Technical Principles of EfficientTAM
- Non-Hierarchical Vision Transformer (ViT): Using a simple, non-hierarchical ViT as the image encoder, compared to traditional multi-stage image encoders, ViT provides more efficient feature extraction.
- Efficient Memory Module: An efficient memory module is introduced to store and utilize information from past frames to assist the segmentation task of the current frame, while reducing memory and computational complexity.
- Memory Cross-Attention Mechanism: EfficientTAM proposes an efficient cross-attention mechanism based on the locality of memory spatial embeddings, which helps reduce the number of parameters and computation in cross-attention calculations.
- Exploiting Locality: Based on the strong locality of memory spatial embeddings, a coarse representation of memory spatial embeddings is created through average pooling, reducing computation without losing accuracy.
- Model Training and Optimization: EfficientTAM is trained on the SA-1B and SA-V datasets, optimized for video object segmentation and tracking tasks, and evaluated on multiple video segmentation benchmarks to ensure the model's generalization ability and practicality.
Project Address of EfficientTAM
- Project Website:yformer.github.io/efficient-track-anything
- GitHub Repository:https://github.com/yformer/EfficientTAM
- HuggingFace Model Library:https://huggingface.co/spaces/yunyangx/EfficientTAM
- arXiv Technical Paper:https://arxiv.org/pdf/2411.18933
Application Scenarios of EfficientTAM
- Mobile Video Editing: On mobile devices such as smartphones, it is used for real-time video editing, such as segmenting specific objects, changing backgrounds, or applying special effects.
- Video Surveillance: EfficientTAM can perform real-time tracking and segmentation of objects in surveillance videos, contributing to security monitoring, crowd counting, and abnormal behavior detection.
- Augmented Reality (AR): In AR applications, it is used for real-time recognition and segmentation of objects in the real world, overlaying virtual information or images for users.
- Autonomous Driving: In autonomous vehicles, it analyzes road conditions in real time, identifying and tracking pedestrians, vehicles, and other obstacles.
- Medical Imaging Analysis: Assisting medical imaging analysis, by segmenting key structures in medical images to help doctors with diagnosis and treatment planning.