
What is EchoMimic
EchoMimic is anAI digital humanopen-source project launched by Alibaba's Ant Group that gives static images vivid speech and expressions. Through deep learning models that combine audio and facial landmarks, it creates highly realistic dynamic portrait videos. It not only supports generating videos using audio or facial features alone, but can also combine the two to achieve more natural and smooth lip-sync effects. EchoMimic supports multiple languages, including Chinese and English, and is suitable for various scenarios such as singing, bringing revolutionary progress to digital human technology, and is widely used in fields such as entertainment, education, and virtual reality.
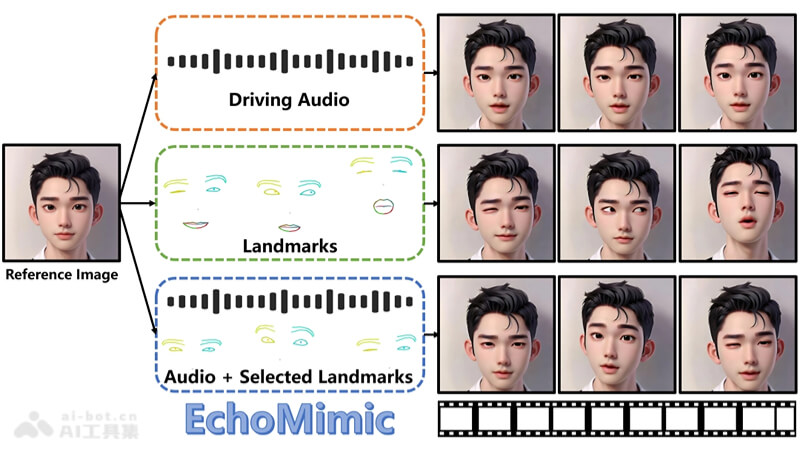
The birth of EchoMimic is not just an attempt by Alibaba in the digital human field, but also an innovation of existing technology. Traditional portrait animation technology either relies on audio-driven or facial keypoint-driven approaches, each with its own advantages and disadvantages. EchoMimic cleverly combines these two driving methods, and through dual training with audio and facial keypoints, achieves more realistic and natural dynamic portrait generation.
EchoMimic's features
- Audio-synchronized animation: By analyzing audio waveforms, EchoMimic can accurately generate lip movements and facial expressions synchronized with speech, giving static images vivid dynamic expression.
- Facial feature fusion: The project uses facial landmark technology to capture and simulate the movement of key parts such as eyes, nose, and mouth, enhancing the realism of the animation.
- Multimodal learning: Combining audio and visual data, EchoMimic improves the naturalness and expressiveness of animation through multimodal learning methods.
- Cross-language capability: Supports multiple languages such as Mandarin Chinese and English, allowing users in different language regions to use this technology to create animations.
- Style diversity: EchoMimic can adapt to different performance styles, including daily conversation, singing, etc., providing users with a wide range of application scenarios.
EchoMimic's official website entrance
- Project official website:https://badtobest.github.io/echomimic.html
- GitHub repository:https://github.com/BadToBest/EchoMimic
- Hugging Face model library:https://huggingface.co/BadToBest/EchoMimic
- arXiv technical paper:https://arxiv.org/html/2407.08136
- EchoMimicV2:EchoMimicV2 Building on the previous generation EchoMimicV1's generation of realistic human head animations, the effect has been further improved, and it can now generate complete digital human half-body animations, achieving seamless conversion from Chinese and English speech to actions.
EchoMimic's technical principles
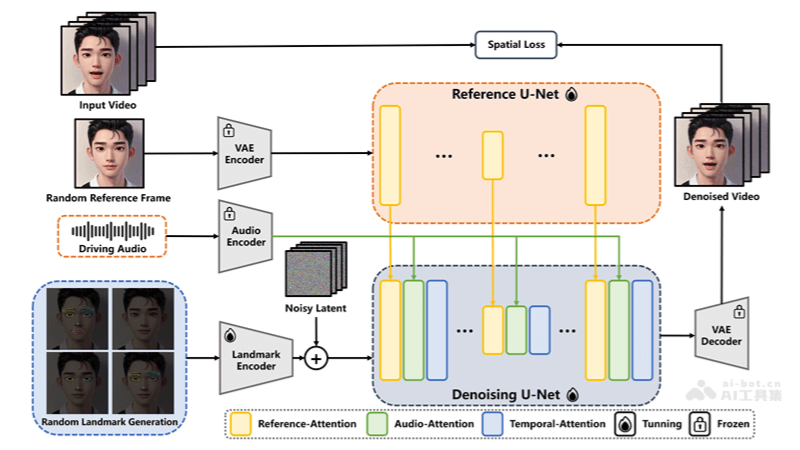
- Audio feature extraction: EchoMimic first conducts an in-depth analysis of the input audio, using advanced audio processing technology to extract key features such as the rhythm, pitch, and intensity of the speech.
- Facial landmark localization: Through high-precision facial recognition algorithms, EchoMimic can accurately locate key facial areas, including lips, eyes, eyebrows, etc., providing a foundation for subsequent animation generation.
- Facial animation generation: Combining audio features and the position information of facial landmarks, EchoMimic uses complex deep learning models to predict and generate facial expressions and lip movement changes synchronized with speech.
- Multimodal learning: The project adopts a multimodal learning strategy, deeply fusing audio and visual information, so that the generated animation is not only visually realistic but also highly consistent with the audio content semantically.
- Application of deep learning models:
- Convolutional Neural Network (CNN): used to extract features from facial images.
- Recurrent Neural Network (RNN): handles the temporal dynamic characteristics of audio signals.
- Generative Adversarial Network (GAN): generates high-quality facial animations, ensuring the realism of the visual effects.
- Innovative Training Method: EchoMimic adopts an innovative training strategy that allows the model to use audio and facial landmark data independently or in combination, in order to improve the naturalness and expressiveness of the animation.
- Pretraining and Real-Time Processing: The project uses a model pretrained on a large amount of data, and EchoMimic can quickly adapt to new audio input and generate facial animations in real time.