
What is EasySpider
EasySpider is an open-source, free, and ad-free visual web scraping tool. The tool supports cross-platform operation (Windows, macOS, Linux) and is based on a graphical interface, allowing users to quickly design and execute scraping tasks without writing code. The tool offers a variety of advanced features, such as dynamic debugging, custom plugins, CAPTCHA recognition, OCR recognition, and proxy IP support, ensuring the security and flexibility of data collection. EasySpider provides a wealth of tutorial resources to help users get started quickly.
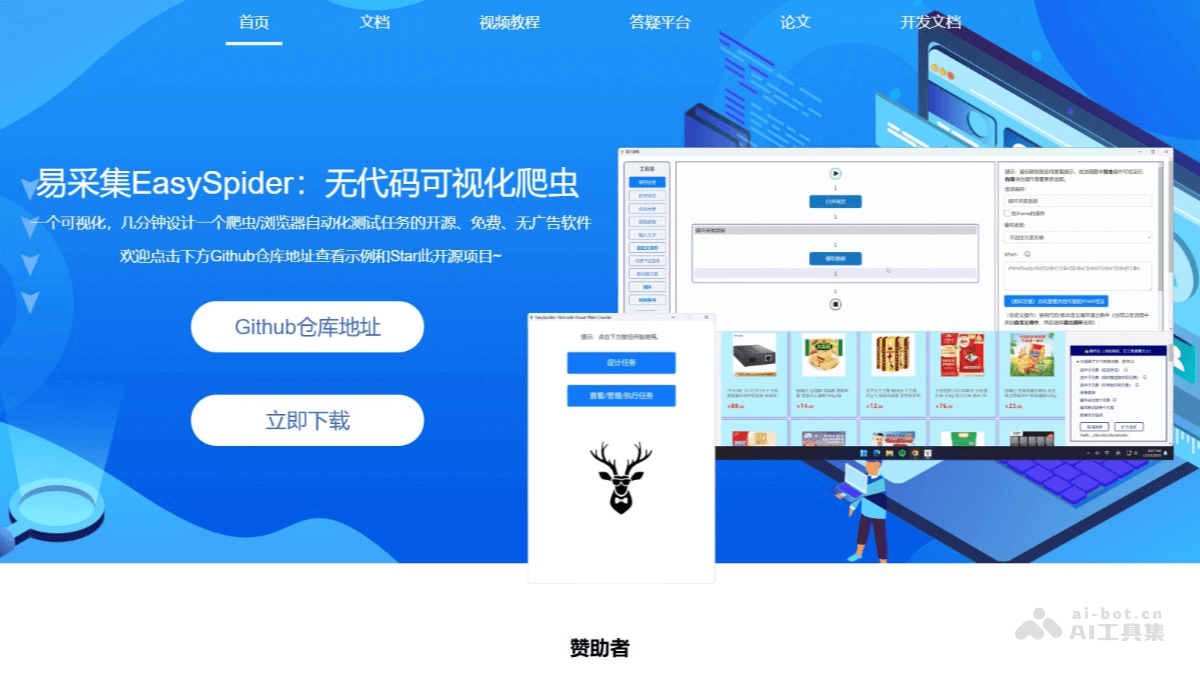
Main Features of EasySpider
- Visual No-Code Design: Based on drag-and-drop and click operations, users can easily design scraping tasks without writing code.
- Multiple Data Types: Supports collecting text, images, PDF, JSON, and other data.
- Element Screenshots and OCR Recognition: Supports taking screenshots of web page elements and recognizing text in images based on OCR technology.
- Dynamic Content Collection: Supports collecting dynamically loaded content, such as data generated with JavaScript.
- Browser Automation: Supports freely adding browser plugins, executing JavaScript commands, and directly manipulating the browser with Selenium statements.
- Support for Multiple Browsers: Compatible with mainstream browsers such as Chrome, Firefox, etc.
EasySpider Project Address
- Project Official Website:https://www.easyspider.net/
- GitHub Repository:https://github.com/NaiboWang/EasySpider
- Technical Paper:https://dl.acm.org/doi/abs/10.1145/3543873.3587345
How to Use EasySpider
- Download and Install: Visit the EasySpider GitHub page or the project official website to download the latest version.
- Install: Choose the appropriate installation package according to your operating system (Windows, macOS, Linux) and install it.
- Launch the Software: After installation is complete, launch the EasySpider software.
- Create a New Task: After launching the software, enter the task manager. Click the "New Task" button to create a new scraping task.
- Design the Scraping Task: Give the scraping task a name for easier future management. Enter the URL of the web page you want to scrape in the task settings.
- Select Elements: Using the graphical interface, right-click the target element on the web page (such as product information, news headlines, etc.) and choose operations such as "Collect Data" or "Select Child Elements".
- Set Collection Rules: Set collection rules as needed, such as looping through and clicking each element, collecting specific fields, etc.
- Save the Task: After finishing the design, click the "Save" button to save your scraping task.
- Debug and Optimize: Click or double-click the completed operation to automatically mark or test run it, making it easy to locate and debug issues. Based on the debugging results, optimize the collection rules and workflow to ensure the accuracy and efficiency of data collection.
- Execute the Task:
- Manual Execution: In the task manager, select the task you have designed and click the "Execute" button to start collecting data.
- Scheduled Execution: Set the task to execute on a schedule, allowing the software to automatically run the task at the specified time.
- Parallel Multi-Instance: Run multiple tasks simultaneously to achieve parallel collection of large-scale data.
- Data Export: After collection is complete, choose to export the data as Excel, CSV, or TXT files, or write it to a MySQL database. The exported data is used for further analysis or storage.
Application Scenarios of EasySpider
- E-commerce Data Collection: Collect product information, prices, user reviews, etc. from e-commerce platforms, for use in market research, price monitoring, and competitor analysis.
- News and Public Opinion Monitoring: Collect news, posts, comments, etc. from news websites and social media platforms, for use in public opinion monitoring and sentiment analysis.
- Academic Research and Literature Collection: Collect paper information, research data, etc. from academic databases, for use in academic research and literature reviews.
- Automated Testing: Automatically test the functionality of Web applications, such as login, registration, form submission, etc., to ensure the stability and reliability of the application.
- Personal Knowledge Management: Collect website content of personal interest and organize it into a personal knowledge base, for use in learning and research.