
What Is EAFormer
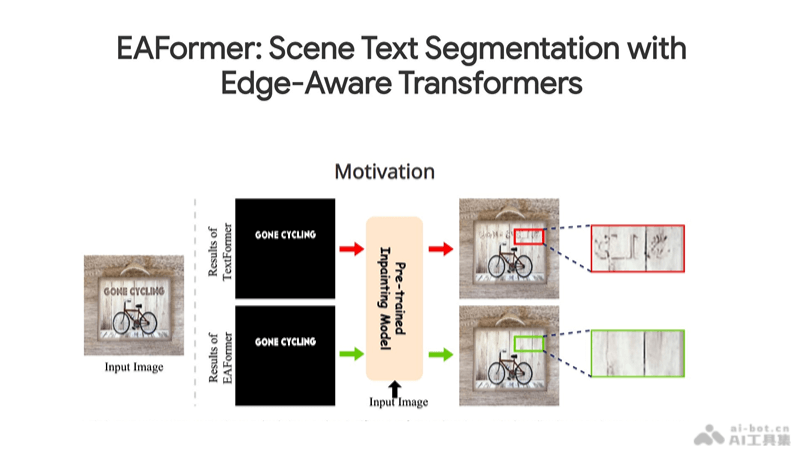
EAFormer is an AI text segmentation framework launched by Fudan University. It excels at finding text in photos and can very precisely separate text from the background. Even when the edges of the text are blurred or the background is complex, EAFormer can do very well. It is very useful for people who want to remove text from images or edit text. EAFormer is an intelligent assistant that lets us easily handle text in images.
EAFormer's Main Features
- Find Text: In photos or images, EAFormer can quickly find all the text.
- Outline Corners: It can not only find text, but also depict the edges of text especially accurately, even where they are curved or irregular.
- Change Background: If you want to remove text from an image and replace it with a new background, EAFormer makes the text look as if it was never there.
- Learn New Tricks: If EAFormer encounters text in a new or different language, it can quickly learn and improve its recognition ability.
EAFormer's Technical Principles
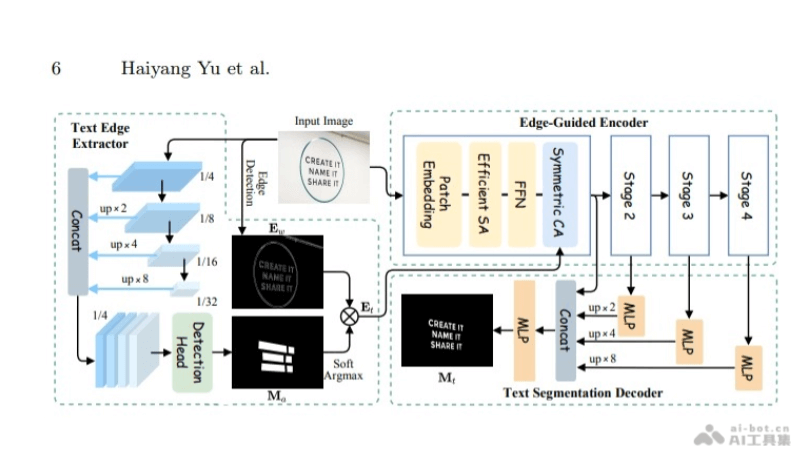
- Text Edge Extractor: Uses the Canny algorithm to detect edges in images, and combines it with a lightweight text detection model to filter out edges in non-text regions, retaining only edge information in text regions.
- Edge-Guided Encoder: Built on the SegFormer framework, it incorporates edge information during the encoding process through symmetric cross-attention layers, enhancing the model's ability to perceive text edges.
- MLP Decoder: Uses multilayer perceptron (MLP) layers to fuse features and predict the final text mask, achieving precise segmentation of text regions.
- Loss Function Design: Uses two cross-entropy losses, text detection loss and text segmentation loss, for optimization, balancing their weights through hyperparameters, simplifying the complexity of hyperparameter selection.
- Dataset Re-annotation: In response to annotation quality issues in datasets such as COCO_TS and MLT_S, re-annotation was carried out to ensure the reliability of evaluation results and the accuracy of model training.
- Feature Fusion Strategy: In the edge-guided encoder, through a designed symmetric cross-attention mechanism, edge information is fused only in the first layer, avoiding the performance degradation that may be caused by fusing edge information in all layers.
- Lightweight Text Detector: Used in the text edge extractor, including a ResNet-based backbone network and an MLP decoder, to extract text region features and assist edge filtering.
EAFormer's Project Address
-
GitHubRepository:https://hyangyu.github.io/EAFormer/
-
arXivTechnical Paper:https://arxiv.org/abs/2407.17020
EAFormer's Application Scenarios
- Scene Text Recognition: Recognize and segment text in natural scenes or images, for information extraction or data mining.
- Image Editing: Assist image editing software in accurately erasing or replacing text in images, maintaining the naturalness and coherence of the background.
- Ad Blocking: Automatically detect and mask advertisements or other unwanted text in video streams or images.
- Copyright Protection: Help identify and protect copyrighted text, preventing unauthorized copying or distribution.
- Document Processing: Automate text recognition during document scanning and digitization, improving the efficiency and accuracy of document processing.