
What is DuoAttention
DuoAttention is a novel framework proposed by the MIT Han Song team to improve the inference efficiency of large language models (LLMs) when processing long contexts. Based on distinguishing two types of attention heads, "retrieval heads" and "streaming heads," it optimizes the model's memory usage and computation speed. Retrieval heads are responsible for handling long-distance dependencies and require a full key-value (KV) cache, while streaming heads focus on recent tokens and attention sinks and only need a fixed-length KV cache. The two types of attention heads allow DuoAttention to reduce memory consumption and improve decoding and pre-filling speed while maintaining model accuracy. Combined with quantization techniques, DuoAttention can achieve context inference of up to 3.3 million tokens on a single GPU, making it an effective solution for processing long text information.
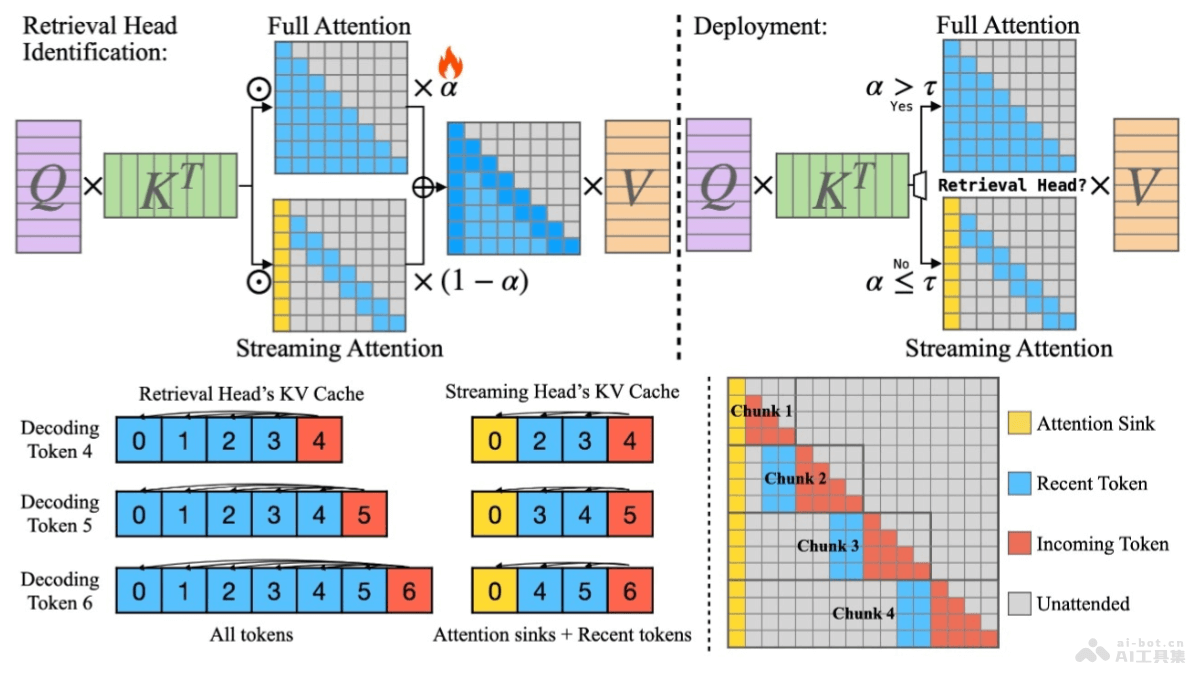
Main features of DuoAttention
- Improve long-context reasoning efficiency: By optimizing the attention mechanism of large language models (LLMs), DuoAttention significantly improves the model's ability to process long-context data.
- Reduce memory consumption: By distinguishing retrieval heads that require a full KV cache from streaming heads that only need a fixed-length KV cache, it reduces the model's memory usage during runtime.
- Accelerate the decoding and pre-filling process: DuoAttention optimizes the model's decoding speed and pre-filling speed, which is crucial for improving the response time and processing efficiency of LLMs.
- Maintain model accuracy: While reducing memory consumption and improving efficiency, DuoAttention can maintain the model's accuracy when handling long- and short-context tasks.
Technical principles of DuoAttention
- Distinguishing attention heads: DuoAttention divides the attention heads in LLMs into retrieval heads and streaming heads. Retrieval heads are responsible for capturing key information in the context and perform full attention processing on all tokens; streaming heads mainly process recent tokens and attention sinks and do not need to store the full historical KV state.
- KV cache optimization for retrieval heads: A full KV cache is retained for retrieval heads to ensure that long-distance dependency information can be captured.
- Lightweight KV cache for streaming heads: Streaming heads use a fixed-length KV cache, reducing memory requirements and supporting efficient processing of long sequence data by the model.
- Automatic identification of retrieval heads: DuoAttention uses optimization-based algorithms and synthetic datasets to train the model, automatically identifying which heads are retrieval heads and allocating appropriate KV cache strategies during inference.
- Synthetic datasets: By designing synthetic datasets and password recall tasks, DuoAttention can determine which attention heads have a significant impact on model output after retaining or discarding the KV cache, optimizing the model's long-context processing capability.
Project address of DuoAttention
- GitHub repository:https://github.com/mit-han-lab/duo-attention
- arXiv technical paper:https://arxiv.org/pdf/2410.10819
Application scenarios of DuoAttention
- Multi-turn dialogue systems: In chatbots or virtual assistants, it processes historical information in multi-turn dialogues, enabling the system to better understand the context and provide more accurate and coherent answers.
- Long document processing: For applications that need to analyze large amounts of text data, such as legal document review, medical research paper reading, or summary generation for long articles, DuoAttention can efficiently process long texts and extract key information.
- Education and research: In academic research, researchers need to analyze a large amount of literature and data. DuoAttention can quickly understand information in a large amount of literature and accelerate the research process.
- Content recommendation systems: In recommendation systems, understand users' historical behavior and preferences to provide more personalized content recommendations.
- Natural language understanding: In complex tasks that require deep understanding of natural language, such as sentiment analysis, intent recognition, etc., DuoAttention can provide deep understanding of long contexts and improve task accuracy.