
What is DreamActor-H1
DreamActor-H1 is a framework launched by ByteDance based on the Diffusion Transformer (DiT), which supports generating high-quality human product demonstrations from paired human and product imagesvideo. The framework injects reference information from both humans and products, using a masked cross-attention mechanism while preserving human identity and product details (such as logos and textures). The framework combines 3D human mesh templates and product bounding boxes to provide precise motion guidance, and uses structured text encoding to enhance 3D consistency. DreamActor-H1 is trained on large-scale mixed datasets and significantly outperforms existing technologies, making it suitable for personalized e-commerce advertising and interactive media.
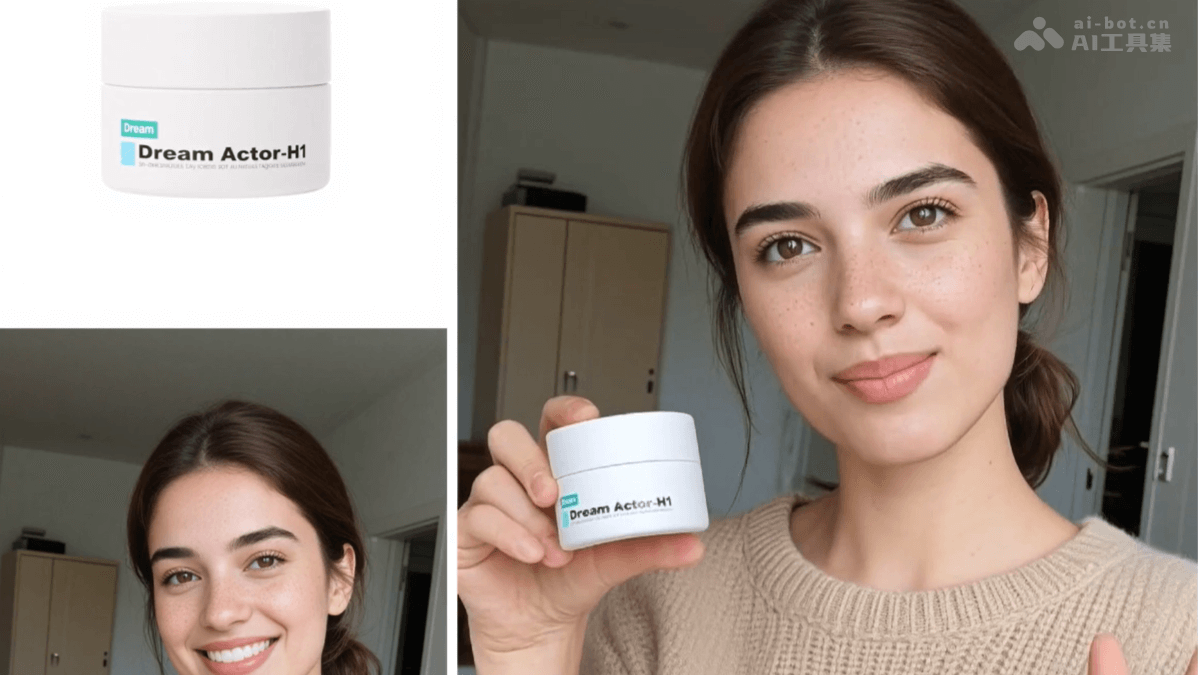
Main features of DreamActor-H1
- High-fidelity video generation: Supports generating high-fidelity, realistic demonstration videos from human images and product images.
- Identity preservation: During video generation, preserves the identity features of humans and the details of products (such as logos, textures, etc.).
- Natural motion generation: Provides precise motion guidance based on 3D body templates and product bounding boxes, generating natural interactive motions.
- Semantic enhancement: Based on structured text encoding, enhances the visual quality and 3D consistency of videos, especially under small rotation changes.
- Personalized applications: Suitable for personalized e-commerce advertising and interactive media, supporting diverse human and product inputs.
Technical principles of DreamActor-H1
- Diffusion Model: Based on the generative capability of diffusion models, gradually generates video content from noise. Diffusion models generate high-quality images or videos by progressively removing noise.
- Masked Cross-Attention: Based on injecting paired human and product reference information, uses a masked cross-attention mechanism to ensure that the details of humans and products in the generated video are accurately preserved.
- 3D motion guidance: Combines 3D body mesh templates and product bounding boxes to provide precise motion guidance for video generation, ensuring natural alignment between hand movements and product placement.
- Structured text encoding: Based on product descriptions and human attribute information generated by a vision-language model (VLM), enhances semantic consistency in video generation and improves visual quality and 3D stability.
- Multimodal fusion: Fuses human appearance, product appearance, and text information into the diffusion model, and based on full attention, reference attention, and object attention mechanisms, achieves high-quality video generation.
Project address of DreamActor-H1
- Project official website:https://submit2025-dream.github.io/DreamActor-H1/
- arXiv technical paper:https://arxiv.org/pdf/2506.10568
Application scenarios of DreamActor-H1
- Personalized product display: Based on generating videos of human-product interaction, displays product usage scenarios and functions, enhancing users' willingness to purchase.
- Virtual try-on: Provides users with virtual try-on experiences, such as virtually trying on clothing or testing cosmetics, helping users better understand product effects.
- Product promotion: Generates high-quality product demonstration videos for e-commerce platforms, used on product detail pages or in advertising placements, enhancing product appeal and sales conversion rates.
- Social media advertising: Generate engaging video content for advertising on social media platforms to increase user engagement and brand exposure.
- Brand promotion: Based on generating videos of brand spokespeople interacting with products, enhance brand image and user identification.