
What is Draw an Audio
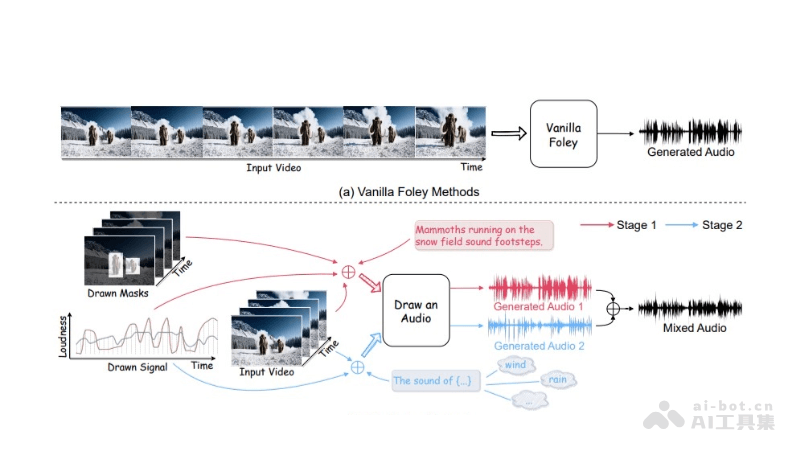
Draw an Audio is a video-to-audio generation system launched by researchers from the Institute of Automation, Chinese Academy of Sciences, and Meituan Dianping. It automatically generates matching sound effects based on video content, similar to the Foley art in film production. The system analyzes videos and combines multiple input instructions, such as text, video masks, and loudness signals, to generate audio consistent with video content, timing, and loudness. The core architecture includes a Latent Diffusion Model (LDM), a text conditioning model, a Masked-Attention Module (MAM), and a Time-Loudness Module (TLM). Together, these components ensure the high quality and accuracy of audio generation. It provides a powerful tool for video content creators, making the sound design process more efficient and flexible.
Main Features of Draw an Audio
- Content Consistency: The system analyzes video content and generates sounds that match the semantics of the video scene, such as generating corresponding animal calls when animals appear in the video.
- Temporal Consistency: The generated audio is precisely synchronized with the actions in the video, ensuring that sound effects appear at the correct time points, for example, the sound of an object collision in the video occurs simultaneously with the collision action.
- Loudness Consistency: The system adjusts the loudness of sounds according to the intensity of actions in the video, such as sounds from distant objects being relatively quieter, while sounds from nearby objects are louder.
- Multi-Instruction Input: The system supports multiple input instructions, including the video itself, relevant text descriptions, video masks, and loudness signals, making audio generation more flexible and controllable.
- High-Quality Synchronized Audio: By utilizing multiple instructions, Draw an Audio can generate high-quality audio that is naturally synchronized with video content, enhancing the viewing experience.
Technical Principles of Draw an Audio
- Latent Diffusion Model (LDM): As the foundational model, it is responsible for the basic generation and processing of audio data.
- Text Conditioning Model: It processes text instructions to ensure that the generated audio matches the text descriptions, improving the semantic consistency of the content.
- Masked-Attention Module (MAM): It uses video masks to focus on key areas of the video, enhancing the consistency between video content and generated audio.
- Time-Loudness Module (TLM): It processes signal instructions, such as loudness signals, to ensure that the generated sound is synchronized with the video in time and loudness.
Project Address of Draw an Audio
- Project Official Website:yannqi.github.io/Draw-an-Audio
- arXiv Technical Paper:https://arxiv.org/pdf/2409.06135
Application Scenarios of Draw an Audio
- Film and Video Production: In film and television post-production, Draw an Audio automatically adds matching sound effects to silent videos, such as footsteps and vehicle sounds, improving production efficiency and reducing costs.
- Game Development: It generates realistic sound effects for animations and scenes in games, enhancing players' immersion and gaming experience.
- Virtual Reality (VR) and Augmented Reality (AR): It generates sounds that match the scene in virtual environments, improving users' interactive experience and perceived realism.
- Education and Training: It automatically generates explanatory sounds for educational videos, helping students better understand and absorb knowledge.
- Animation Production: Automatically generate dialogue and environmental sound effects for animated characters, making animation production more efficient.
- Advertising Production: Generate engaging audio effects for advertising videos, enhancing the appeal and memorability of advertisements.