
What is Doubao Audio Generation Model 1.0
Doubao Audio Generation Model 1.0 (Seed Audio 1.0) is an end-to-end audio creation model launched by Volcano Engine, supporting text or audio as reference input to generate target audio. A single Prompt can orchestrate multi-character dialogue, emotional tone, background music, and environmental atmosphere, directly producing a complete audio work with narrative tension without the need for post-production multi-track mixing. The model maintains highly consistent timbre during long-duration generation, supports decoupled control of timbre and style, and covers scenarios such as audio dramas, podcasts, and brand audio.
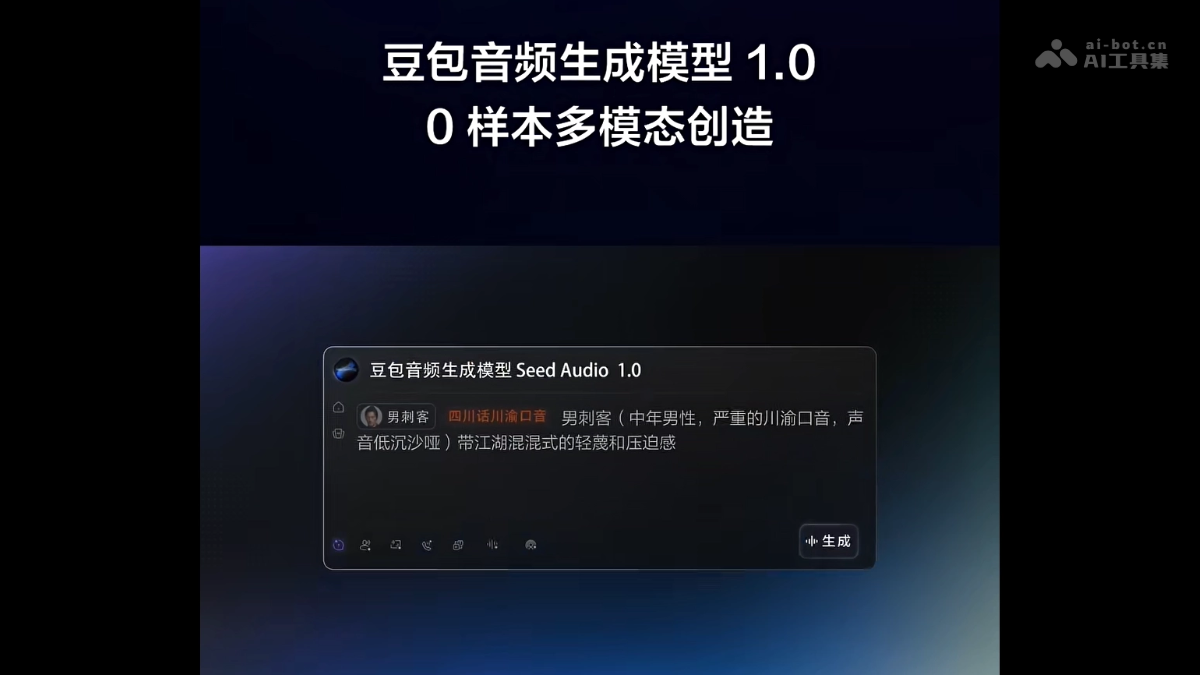
Main features of Doubao Audio Generation Model 1.0
-
Reference generation: Supports text descriptions or reference audio as input, generating target audio end-to-end without additional training.
-
Full-element orchestration: Simultaneously defines character dialogue, emotional tone, background music, and environmental sound effects within a single Prompt, with the output being the final product.
-
Multi-character consistency: Supports multi-character timbre definition and long-duration consistency maintenance, avoiding the "role confusion" problem in long audio.
-
Non-verbal expression: Accurately reproduces details such as laughter, sighs, pauses, and dialect accents, enhancing the vitality of dialogue.
-
Timbre-style decoupling: The same timbre can adapt to different emotions and scenarios, supporting differentiated expression of "one voice, multiple roles".
-
Audio extension: Performs multiple extensions based on 2-minute reference audio, maintaining highly unified timbre.
Technical principles of Doubao Audio Generation Model 1.0
- End-to-end multimodal generation: The model adopts a unified end-to-end architecture, encoding text descriptions and audio references into shared latent space representations, and directly generating target audio waveforms through a decoder, avoiding the traditional pipeline architecture of TTS + sound effects + music track-by-track synthesis and achieving integrated generation of vocals, soundtrack, and environmental sound.
- Long-duration timbre consistency mechanism: By deeply linking the latent space features of text-to-audio and reference audio, the model locks the timbre anchor during multiple audio extensions, ensuring that the character's voice features remain highly consistent from the 1st minute to the 10th minute, meeting the long-range generation needs of audiobooks, long drama series, and more.
- Decoupled control of timbre and style: The model separates timbre identity features from emotional expression style into different subspaces, supporting flexible switching of the same speaker's timbre across different emotions and contexts, while also achieving one voice, multiple roles, meaning the same voice foundation presents differentiated expression under different character settings.
How to use Doubao Audio Generation Model 1.0
- Visit the platform: Open the Volcano Ark official website and log in with a ByteDance account, then enter the "Experience Center".
- Select the model: Under the speech model category, find speech synthesis and select the Doubao-Audio-Generation-1.0 model.
- Describe the scene: Write a prompt in the input box, specifying elements such as characters, lines, emotions, sound effects, and environmental sounds, and you can specify the timeline for each sound's entrance.
- Control the timbre: Directly describe the target timbre in text, or upload reference audio to further precisely control the generation result, without the need to train a model separately.
- Generate audio: Click the generate button, and the model will output a complete sound scene end-to-end based on the unified framework.
- Extension and Export: For long audio, you can continue extending the generation based on existing results while maintaining character consistency; once satisfied with the preview, export the final audio file.
Core Advantages of Doubao Audio Generation Model 1.0
-
All-Element Integrated Generation: Say goodbye to the cumbersome process of separately producing vocals, sound effects, and music and then compositing and editing them; a single Prompt directly produces finished-level audio.
-
Long-Duration Timbre Consistency: Solves the core pain point of inconsistent character voices before and after in long audio creation, and supports multiple extensions without the need to retune segment by segment.
-
Zero-Shot Multimodal Creation: Supports both text and audio dual-modal input, and can generate high-quality target audio without additional training, greatly lowering the creation threshold.
-
Fine-Grained Decoupling of Timbre and Style: The same timbre can adapt to multiple emotions and roles, enabling flexible “one voice, multiple roles” expression and enhancing the freedom of dubbing and performance.
Project Address of Doubao Audio Generation Model 1.0
- Project Website:https://seed.bytedance.com/zh/seedaudio1_0
- Technical Paper:https://seed.bytedance.com/zh/blog/from-speech-to-audio-creation-introducing-the-seed-audio-1-0-audio-creation-model
Comparison of Doubao Audio Generation Model 1.0 with Similar Competing Products
| Comparison Dimension | Doubao Audio Generation Model 1.0 | AudioX-Turbo |
|---|---|---|
| Core Positioning | End-to-end all-element audio creation (integrated vocals + music + sound effects) | Multimodal audio generation and editing (text/image/video/audio → audio) |
| Input Modalities | Text descriptions, reference audio | Four modalities: text, image, video, audio |
| Multi-Role Arrangement | A single Prompt supports unified arrangement of multi-role dialogue, tone, and emotion | Mainly focuses on single-audio generation, with limited ability to arrange long multi-role dialogue |
| Timbre Consistency | Supports multiple extensions of long-duration audio, maintaining a high degree of character timbre consistency | Strong single-generation capability, but long-duration consistency extension is not explicitly supported |
| All-Element Generation | Integrated output of dialogue, background music, and environmental sound effects without post-production mixing | Generates audio content, but integrated music/sound effects/vocals finished-production capability is relatively weak |
| Timbre-Style Decoupling | Supports the same timbre adapting to different emotions and “one voice, multiple roles” | Supports style transfer, but character-level timbre decoupling control is relatively coarse |
| Chinese Optimization | Native Chinese context optimization, supports dialect accents | General multilingual support, with slightly weaker detailed Chinese expression |
| Usage Threshold | Prompt-driven, zero-shot creation, directly experienceable on Volcengine Ark | Requires a certain technical foundation, mainly GitHub open-source deployment |
Application Scenarios of Doubao Audio Generation Model 1.0
-
Audio Dramas and Podcasts: Creators directly generate complete audio works with multi-role dialogue, background music, and sound effects through Prompts, eliminating post-production mixing.
-
Brand Audio Advertising: Quickly produce brand audio materials including narration, soundtrack, and ambient sound, shortening the advertising production cycle.
-
Long Audio Content: Audiobooks and long serialized drama series use the timbre consistency extension function to keep character voices consistent throughout.
-
Livestream E-commerce Audio: Generate product-selling script audio with specific accents and emotional pacing, adapting to different products and host styles.
-
Film and TV pre-dubbing: Quickly generate temporary dialogue and ambient sound for film and TV clips, assisting with early-stage editing and storyboard confirmation.