
What is DITTO-2
DITTO-2 is a new type jointly launched by researchers from Adobe and the University of Californiamusic generationmodel that achieves fast and controllable music generation by optimizing the inference time of diffusion models. The model is based on Inference-Time Optimization (ITO) of diffusion models and, through model distillation techniques such as Consistency Model (CM) and Consistency Trajectory Model (CTM), increases generation speed to faster than real time. DITTO-2 supports a variety of music generation tasks, including music inpainting, outpainting, intensity control, melody control, and music structure control. It can also convert an unconditional diffusion model into a model with advanced text control capabilities, achieving high-quality text-to-music generation by maximizing the CLAP score.
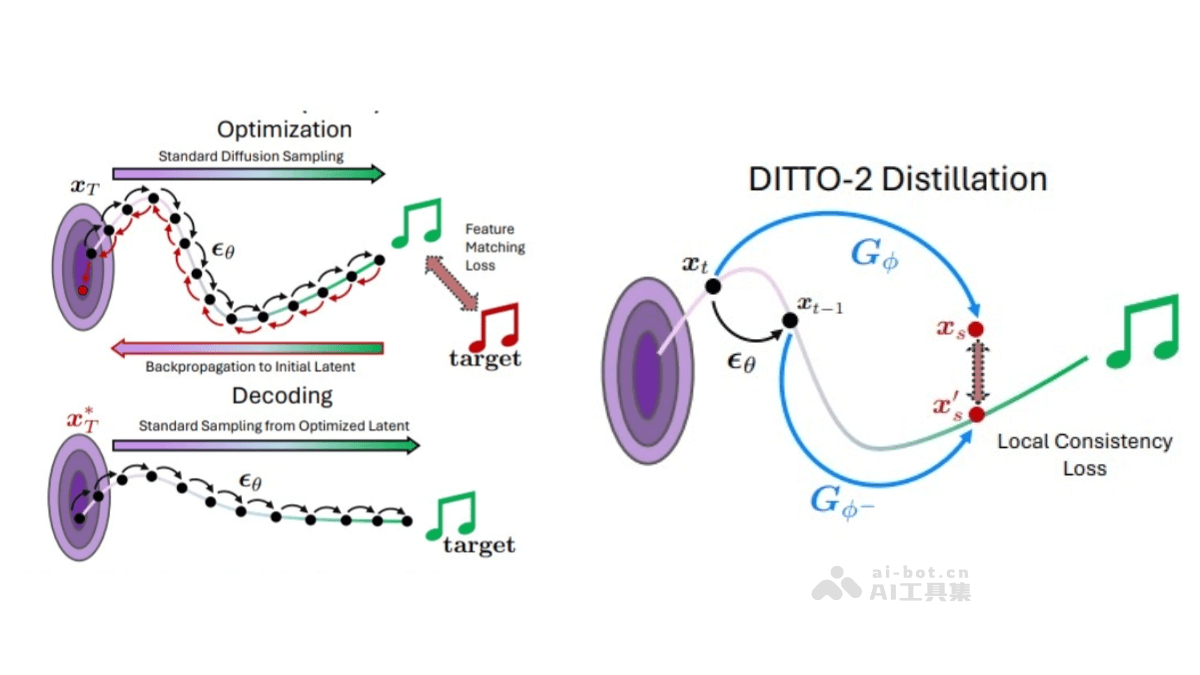
Main Features of DITTO-2
- Music Inpainting and Outpainting: DITTO-2 supports music inpainting and outpainting, and can fill in or continue existing music segments.
- Intensity Control: Users can specify the intensity change curve of the music, for example, an intensity change from low to high or from high to low.
- Melody Control: By inputting a reference melody, DITTO-2 can generate music that matches it.
- Music Structure Control: Supports control over music structure, for example, defining the durations of section A and section B.
- Text-to-Music Generation: DITTO-2 can convert an unconditional diffusion model into a model with advanced text control capabilities, achieving high-quality text-to-music generation by maximizing the CLAP score.
- Efficient Inference and Optimization: Through model distillation techniques such as Consistency Model CM and Consistency Trajectory Model CTM, DITTO-2 increases generation speed to faster than real time while improving control adherence and generation quality.
Technical Principles of DITTO-2
- Diffusion Model Distillation: DITTO-2 uses two model distillation techniques: Consistency Model (CM) and Consistency Trajectory Model (CTM). CM distills the base diffusion model into a new network with single-step sampling, trained by minimizing the local consistency loss between the learned model and an exponential moving average copy. CTM further extends the capabilities of CM, allowing jumps between any two points on the diffusion trajectory, thereby providing a more efficient sampling path.
- Inference-Time Optimization (ITO): DITTO-2 uses Inference-Time Optimization (ITO) to adjust the model state in real time during the generation process, better conforming to control conditions or objectives. The core of ITO is optimizing the initial noise latent variable, adjusting the model state through feature extraction functions, matching loss functions, and optimization algorithms such as gradient descent, achieving precise control over music intensity, melody, structure, and more.
- Surrogate Optimization and Multi-Step Decoding: DITTO-2 introduces surrogate optimization, separating the optimization process from the final decoding process. The optimization stage uses single-step sampling to quickly estimate the noise latent variable, while the decoding stage generates high-quality music through multi-step sampling. This separated method significantly improves the quality of generated music while maintaining fast inference.
- Efficient Training and Applications: DITTO-2 has low training costs, requiring only over 30 hours of training on A100 GPUs. DITTO-2 also supports a variety of music generation tasks, including music infilling, extension, intensity control, melody control, and musical structure control.
DITTO-2 project address
- Project website:https://ditto-music.github.io/ditto2
- arXiv technical paper:https://arxiv.org/pdf/2405.20289
DITTO-2 application scenarios
- Music creation and generation: DITTO-2 can generate high-quality music from text descriptions. The model can generate music that matches the description.
- Real-time music generation: DITTO-2's generation speed is faster than real time, making it suitable for scenarios that require rapid music generation, such as real-time music creation or live performance.
- Music educators and students: DITTO-2 can generate sample music in real time, helping students better understand and learn music theory. Teachers can quickly generate sample music for teaching demonstrations by inputting specific melodies or chord structures.
- Audiobook and multimedia content creators: DITTO-2 supports converting text descriptions into music, and supports generating background music for audiobooks, podcasts, or multimedia projects.