
What is DeepEyesV2
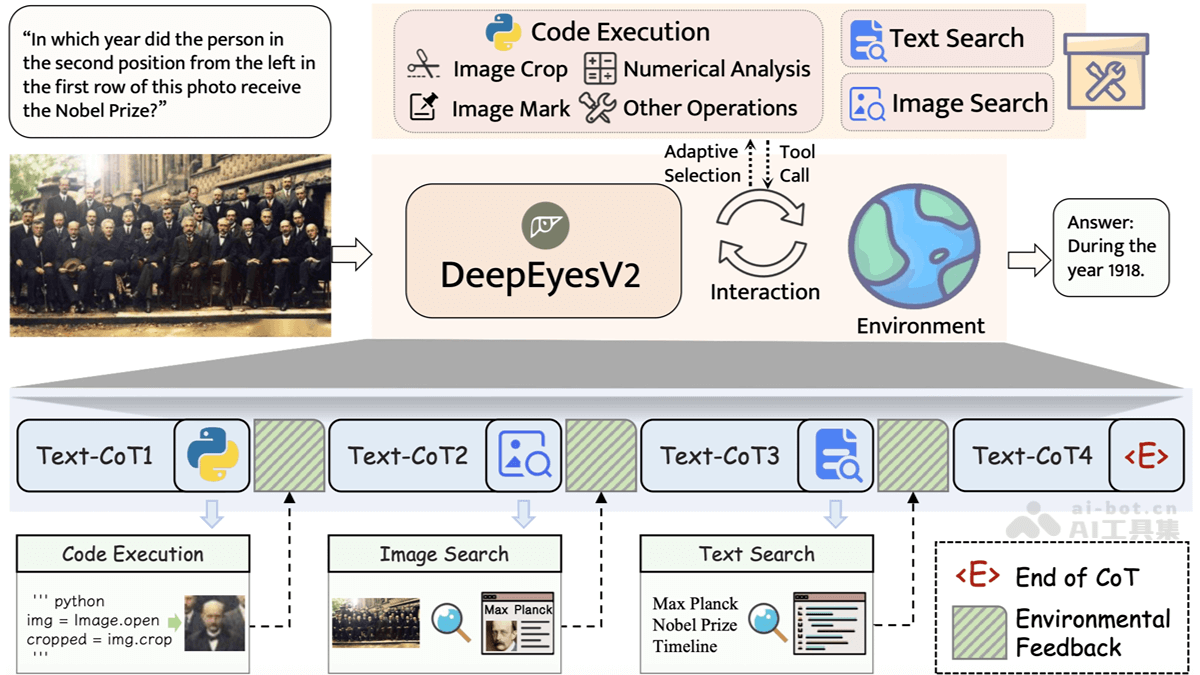
DeepEyesV2 is a multimodal agent model launched by the Xiaohongshu team, achieving powerful tool-calling and multimodal reasoning capabilities through a two-stage training method. The model can understand image-text information, supports proactively invoking external tools such as code execution and web search, and integrates the results returned by tools into the reasoning process to solve complex real-world problems. In the first stage, the model establishes a basic understanding of tool use through supervised fine-tuning; in the second stage, reinforcement learning improves the model's tool-calling efficiency and generalization ability. DeepEyesV2 performs excellently on the newly proposed RealX-Bench benchmark, demonstrating strong multi-skill coordination capabilities.
DeepEyesV2's Main Features
-
Multimodal Understanding: The model can process text and image information simultaneously, understanding complex image-text content.
-
Proactive Tool Invocation: Proactively invokes external tools when needed, such as code execution environments and web search, to obtain additional information or perform complex tasks.
-
Dynamic Reasoning and Decision-Making: Integrates the results of tool calls into the reasoning process, solving problems step by step through iteration.
-
Task Adaptability: Intelligently selects appropriate tools based on different task types (such as perception, reasoning, etc.), improving efficiency and accuracy.
-
Complex Task Solving: Through the combination of tools and iterative reasoning, it solves complex tasks that require the coordination of multiple capabilities, such as comprehensive tasks combining perception, search, and reasoning.
DeepEyesV2's Technical Principles
-
Cold Start Stage:
-
Supervised Fine-tuning (SFT): Fine-tunes the model with a large amount of sample data containing tool-use steps (such as perceptual, reasoning, and long chain-of-thought data), helping the model establish a basic understanding of tool use.
-
Data Design: The data covers multiple task types, ensuring that the model can learn appropriate tool-calling strategies in different scenarios.
-
-
Reinforcement Learning Stage:
-
Policy Optimization: On the basis of the cold start, reinforcement learning further optimizes the model's tool-calling strategy, improving efficiency and generalization ability.
-
Goal: Reduce unnecessary tool calls while creatively combining tools in unseen complex scenarios, improving the model's flexibility and adaptability.
-
DeepEyesV2's Project Address
- Project Website:https://visual-agent.github.io/
- GitHub Repository:https://github.com/Visual-Agent/DeepEyesV2
- arXiv Technical Paper:https://arxiv.org/pdf/2511.05271
DeepEyesV2's Application Scenarios
-
Intelligent Q&A and Information Retrieval: When users upload images and ask questions, DeepEyesV2 can combine image recognition and web search to provide accurate answers.
-
Education and Learning Assistance: Through image recognition and reasoning, it provides students with homework tutoring and knowledge exploration support.
-
Content Creation and Editing: Analyzes image content, provides image editing suggestions, and generates related copy.
-
Intelligent Customer Service and Technical Support: Uses image recognition and web search to provide users with fault diagnosis and consultation answers.
-
Healthcare: Assist doctors in analyzing medical images, and provide health consultation and preliminary diagnosis combined with web search.