
What is DCLM-7B
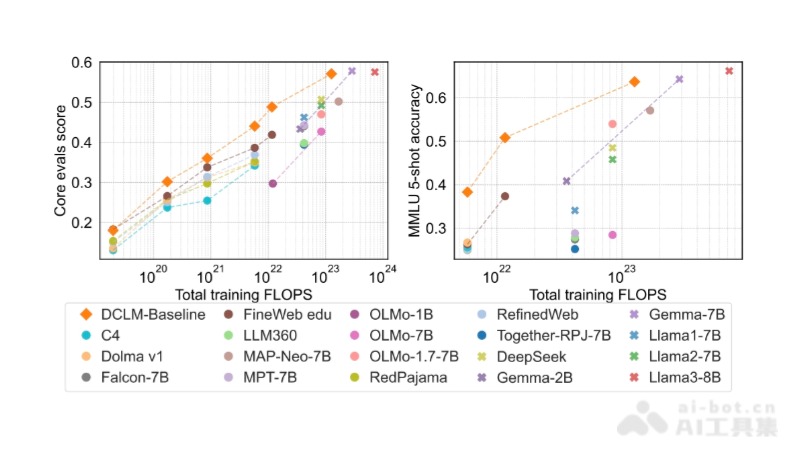
DCLM-7B is a 7-billion-parameter open-source small model launched by Apple in collaboration with a research team. Its performance surpasses Mistral-7B and approaches Llama 3 and Gemma. Recently, Apple, as one of the research institutions of the DataComp-LM (DCLM) project, released the DCLM-7B open-source model on Hugging Face. Based on 240T Common Crawl data and pre-trained through the standardized DCLM-POOL and OpenLM frameworks, the model achieved 64% 5-shot MMLU accuracy, with significantly efficient training. The open-sourcing of DCLM-7B includes weights, training code, and datasets, advancing the LLM open-source community and providing the high-quality dataset DCLM-BASELINE, setting a new benchmark for data-driven model research.
Technical Principles of DCLM-7B
- Large-scale dataset: DCLM-7B uses a standardized corpus of 240 trillion tokens extracted from Common Crawl, providing the model with abundant training data.
- Data filtering: Filtering high-quality training data from large-scale datasets through model-based filtering methods is a key step in building DCLM-7B.
- OpenLM framework: Based on the OpenLM framework, DCLM-7B adopts an effective pre-training scheme, providing a standardized training process and hyperparameter settings.
- Standardized evaluation: DCLM-7B was standardized evaluated on 53 downstream tasks, helping to quantify the advantages and limitations of the training set.
- Model architecture: DCLM-7B uses a decoder-only Transformer model architecture, a deep learning architecture commonly used for language models.
- Training optimization: During training, DCLM-7B uses specific optimization techniques, such as z-loss, to maintain the numerical stability of output logits.
- Multi-scale training: DCLM-7B was trained at different computational scales, from 412M to 7B parameter models, helping to understand the impact of different training scales on model performance.
Project Address of DCLM-7B
- Project official website:https://huggingface.co/apple/DCLM-7B
- GitHub repository:https://github.com/mlfoundations/dclm
- arXiv technical paper:https://arxiv.org/pdf/2406.11794
Suitable Audiences for DCLM-7B
- AI researchers: Scientists and scholars focusing on the fields of natural language processing and machine learning.
- Software developers: Technical personnel integrating advanced language processing capabilities into applications.
- Data analysts: Professionals who process and analyze large amounts of text data to gain insights.
- Educational technology specialists: Educators developing educational tools and interactive learning experiences.
- Enterprise decision-makers: Business leaders using AI to optimize business processes and enhance customer service.