
What is CosyVoice
CosyVoice is an open-source naturalspeech synthesislarge model from Alibaba Tongyi Laboratory. The model supports five languages: Chinese, English, Japanese, Cantonese, and Korean. With only 3 to 10 seconds of audio samples, it can replicate similar timbres, including intonation and emotional details, and can synthesize across languages. The model's highlight is that it can finely control speech emotion and prosody through rich text or natural language input, making synthesized speech lifelike and full of emotional color, far surpassing traditional models. It is widely used in voice broadcasting, audiobooks, voice interaction, and other fields, providing users with a highly personalized and emotional voice experience.
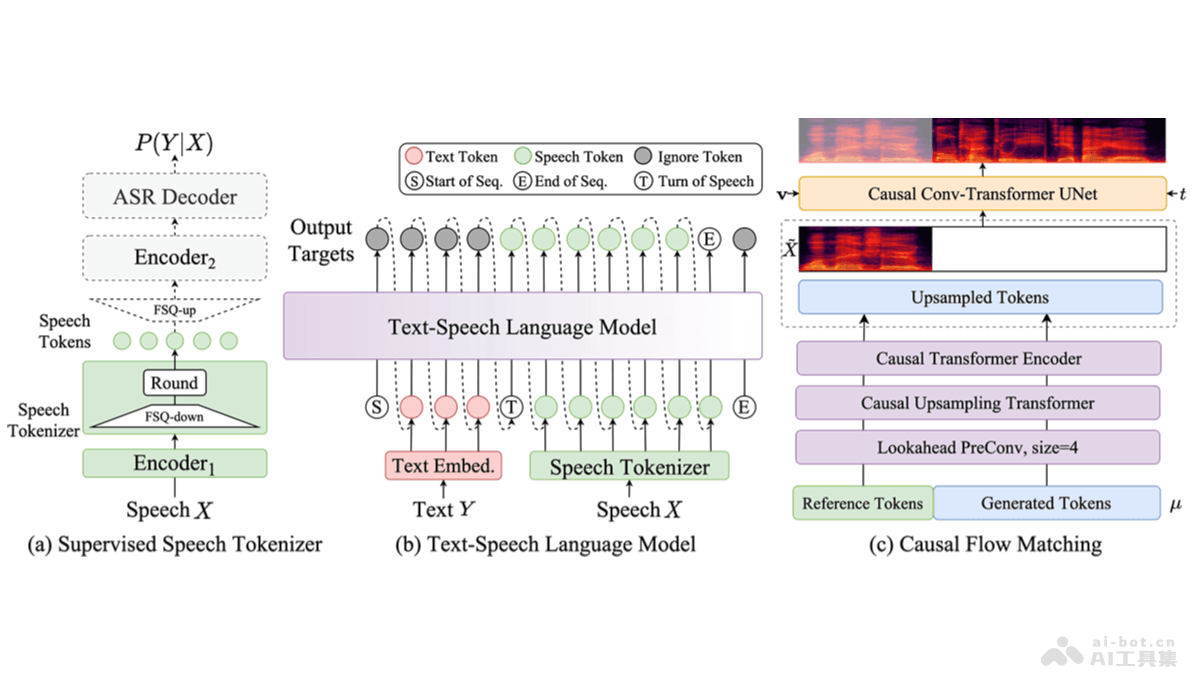
CosyVoice 2.0 is an upgraded version of the CosyVoice large speech generation model launched by Alibaba Tongyi Laboratory. The model uses finite scalar quantization technology to improve codebook utilization, simplifies the text-to-speech language model architecture, and introduces a chunk-aware causal flow matching model to support diverse synthesis scenarios. CosyVoice 2 has significantly improved pronunciation accuracy, timbre consistency, prosody, and sound quality. Its MOS evaluation score increased from 5.4 to 5.53, and it supports streaming inference, greatly reducing the first-packet synthesis latency to 150ms, making it suitable for real-time speech synthesis scenarios.
CosyVoice 3 has been fully upgraded to give voices more emotion and expressiveness. It integrates voice cloning and speech synthesis. Users only need to provide a 3-second voice sample, and it can accurately capture the user's timbre, intonation, and speaking habits, supporting the use of the user's voice to read any text. CosyVoice 3 supports 9 languages including Chinese, English, and Japanese. It can generate speech with specific emotions based on text or instructions, such as "happy," "sad," and "angry," making speech more vivid and expressive. CosyVoice 3 can preserve the accent in the user's voice, making the accent part of the user's digital identity. The model is now available onAlibaba Cloud Model Studio。
Recently, Tongyi Laboratory has made multiple upgrades to CosyVoice3, including reducing the first-packet latency by 50%, doubling the accuracy of mixed Chinese and English characters, and supporting 9 general languages, 18 dialect accents, as well as cross-language cloning and emotional control. In addition, Fun-CosyVoice3-0.5B is officially open-sourced, providing zero-shot timbre cloning capability. With only a 3-second recording, it can replicate the timbre and synthesize new speech. It also supports local deployment and secondary development, providing developers with a powerful speech synthesis tool.
Main Features of CosyVoice
- Ultra-low-latency streaming speech synthesis: Supports bidirectional streaming speech synthesis, with first-packet synthesis latency as low as 150ms, suitable for real-time application scenarios.
- High-accuracy pronunciation: Compared with previous versions, the pronunciation error rate has dropped significantly, especially in handling tongue twisters, polyphonic characters, and rare characters.
- Timbre consistency: Maintains high timbre consistency in zero-shot and cross-language speech synthesis, improving synthesis naturalness.
- Natural experience: The prosody, sound quality, and emotion matching of synthesized audio have been improved, and the MOS evaluation score has increased, approaching commercial large speech synthesis models.
- Multilingual support: Trained on large-scale multilingual datasets to achieve cross-language speech synthesis capability.
Technical Principles of CosyVoice
- LLM backbone: Based on a pre-trained text foundation large model (such as Qwen2.5-0.5B), replacing the original Text Encoder + random Transformer structure for semantic modeling of text.
- FSQ Speech Tokenizer: Replaces vector quantization (VQ) with finite scalar quantization (FSQ), trains a larger codebook (6561), achieves 100% activation, and improves pronunciation accuracy.
- Integrated offline and streaming modeling solution: Propose an integrated modeling solution that enables both LLM and FM to support streaming inference, achieving rapid synthesis of the first audio packet.
- Upgrade of instruction-controllable audio generation capabilities: Optimize the integration of the base model and the instruction model, support emotion, speaking style, and fine-grained control instructions, and add Chinese instruction processing capabilities.
- Multimodal large model technology: Based on multimodal large model technology, realize AI technologies such as speech recognition, speech synthesis, and natural language understanding, providing an intelligent human-computer interaction experience that can "listen, speak, and understand you."
CosyVoice project address
- Project official website:https://funaudiollm.github.io/cosyvoice2/
- GitHub repository:https://github.com/FunAudioLLM/CosyVoice
- HuggingFace model library:https://huggingface.co/FunAudioLLM/Fun-CosyVoice3-0.5B-2512
- Technical paper:https://funaudiollm.github.io/pdf/CosyVoice_2.pdf
- CosyVoice 3 technical paper:https://arxiv.org/pdf/2505.17589
CosyVoice application scenarios
- Intelligent assistants and chatbots: Provide natural and fluent voice output for intelligent assistants and chatbots, improving the user experience.
- Audiobooks and audio books: Generate high-quality audiobooks, support multiple languages and dialects, and meet the needs of different users.
- Video dubbing and narration: Provide dubbing services for video content, including dubbing for educational videos, corporate promotional videos, movies, and TV dramas.
- Customer service and call centers: Provide voice interaction in customer service, improving service efficiency and customer satisfaction.
- Language learning and education: Assist language learning, provide voice demonstrations with standard pronunciation, and help learners improve pronunciation accuracy.