
What is ConsistentDreamer
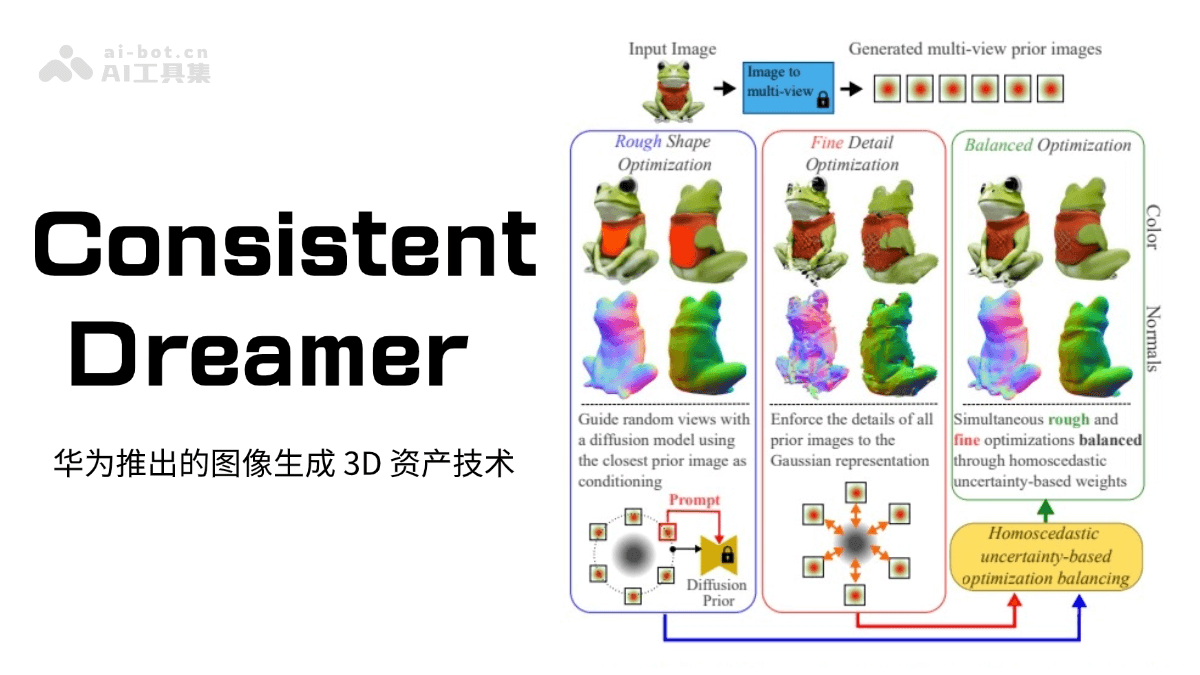
ConsistentDreamer is a new image-to- 3D asset generationtechnology proposed by Huawei's Munich Research Center, which generates view-consistent 3D meshes from a single image. The method uses multi-view prior image-guided Gaussian optimization to address the shortcomings of traditional methods in multi-view consistency. ConsistentDreamer first generates a set of multi-view images from fixed viewpoints, and then optimizes the coarse shape of the 3D model based on score distillation sampling (SDS) loss and a diffusion model. By dynamically balancing task weights between coarse shape and fine detail optimization, it introduces opacity, depth distortion, and normal alignment losses to refine the surface.
Main features of ConsistentDreamer
- 3D consistency enhancement: By introducing 3D-consistent structured noise and self-supervised consistency training, ConsistentDreamer can maintain highly consistent editing results across different views, solving the inconsistency problem of traditional 2D diffusion models in multi-view generation.
- High-resolution texture generation: The framework can generate editing results with fine textures and high clarity, performing excellently in complex scenes (such as large-scale indoor scenes in ScanNet++).
- Complex pattern editing capability: ConsistentDreamer is the first method that can successfully edit complex patterns (such as plaid or checkered patterns).
- Multi-view context input: By taking surrounding views as input, ConsistentDreamer provides rich contextual information for 2D diffusion models, enhancing the model's 3D perception capability.
- Parallelized editing process: ConsistentDreamer uses multi-GPU parallel processing and achieves efficient scene editing by separating NeRF fitting and diffusion model generation.
- Instruction-guided scene editing: The framework supports editing 3D scenes according to natural language instructions, generating high-quality results that are highly consistent with the instructions.
Technical principles of ConsistentDreamer
- Multi-view prior image guidance: ConsistentDreamer first generates a set of multi-view prior images from fixed viewpoints based on a multi-view generation model from a single input image. The images serve as references during the optimization process, providing rich contextual information for the generation of the 3D model.
- Score distillation sampling (SDS): The coarse shape of the 3D model is optimized through score distillation sampling (SDS) loss. Specifically, random views are generated based on a pre-trained diffusion model (such as Zero-1-to-3), and consistency between views is ensured by selecting the prior image closest to the target view as the condition.
- Dynamic task weight balancing: To balance coarse shape optimization and fine detail optimization, ConsistentDreamer introduces dynamic task weights based on homoscedastic uncertainty. They are automatically updated in each iteration to ensure the stability and efficiency of the optimization process.
- Opacity, depth distortion, and normal alignment losses: To improve the quality of mesh extraction, ConsistentDreamer introduces opacity loss, depth distortion loss, and normal alignment loss. They help refine the surface and ensure that the generated 3D mesh has a clear surface and high-quality textures.
- Multi-view context input and consistency training: ConsistentDreamer takes surrounding views as input, provides rich 3D contextual information for the diffusion model, and further strengthens 3D perception capability through self-supervised consistency training.
ConsistentDreamer's project address
- arXiv technical paper:https://arxiv.org/pdf/2502.09278
Application scenarios of ConsistentDreamer
- High-fidelity editing of complex scenes: ConsistentDreamer is suitable for complex large-scale indoor scenes (such as scenes in the ScanNet++ dataset), and can generate editing results with fine textures and high clarity.
- Diverse style transfer: It supports a variety of style transfer tasks, such as converting a scene into a specific artistic style (such as Van Gogh or Munch style), while preserving the details and textures of the original scene.
- Object-specific editing: ConsistentDreamer can edit specific objects in a scene, such as changing a person's expression or the color of an object.
- Cross-view and cross-batch consistency: By introducing structured noise and self-supervised consistency training, ConsistentDreamer can maintain consistency across generation processes in different views and different batches.