What is CodeGemma
CodeGemma is a large language model released by Google focused on code generation and understanding. The series includes three models of different scales: a 2B pretrained model, a 7B pretrained model, and a 7B instruction-tuned model, aimed at providing intelligent code completion, generation, and natural language understanding. Based on Google's previously releasedGemmamodel, CodeGemma has been trained on a large amount of English programming and mathematical data to enhance logical and mathematical reasoning capabilities, supports multiple programming languages, and can be integrated into development environments, simplifying the code writing process and improving development efficiency.
CodeGemma's official website entry
- Official model introduction:https://ai.google.dev/gemma/docs/codegemma
- Hugging Face model address:https://huggingface.co/collections/google/codegemma-release-66152ac7b683e2667abdee11
- Kaggle model address:https://www.kaggle.com/models/google/codegemma
- Technical report:https://storage.googleapis.com/deepmind-media/gemma/codegemma_report.pdf
CodeGemma's functional features
- Code completion: CodeGemma can automatically complete code snippets, including functions, methods, and entire code blocks, helping developers improve coding efficiency.
- Code generation: Based on given context and instructions, CodeGemma can generate new code, which is very useful for rapid prototyping and solving programming problems.
- Natural language understanding: CodeGemma combines natural language processing capabilities and can understand and interpret natural language instructions, making interaction with the model more intuitive and natural.
- Multilingual support: Supports multiple programming languages, including but not limited to Python, JavaScript, Java, etc., enabling it to serve a broader developer community.
- High accuracy: The CodeGemma model is trained on 500 billion tokens of data from web documents, mathematics, and code (mainly English). The generated code is not only syntactically correct but also more semantically meaningful, thereby reducing errors and shortening debugging time.
- Integrated development environment: CodeGemma can be integrated into various development environments, reducing the workload of writing boilerplate code and allowing developers to focus more on innovation and writing core code.
CodeGemma's model series
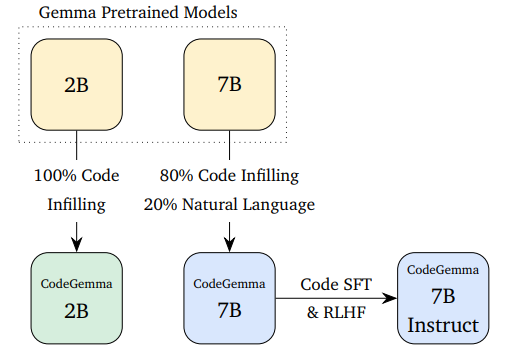
- CodeGemma 2B base model: The 2 billion parameter model is specifically trained for code infilling, aimed at providing fast code completion and generation, especially suitable for environments with high latency and privacy requirements.
- CodeGemma 7B base model: The training data of the 7 billion parameter model contains 80% code infilling data and 20% natural language data, enabling it not only to perform code completion but also to understand and generate code and language.
- CodeGemma 7B Instruct model: Based on CodeGemma 7B, the CodeGemma 7B Instruct model has been further fine-tuned to optimize instruction-following capabilities, suitable for dialogue scenarios, especially when discussing topics such as code, programming, or mathematical reasoning.
CodeGemma's performance evaluation
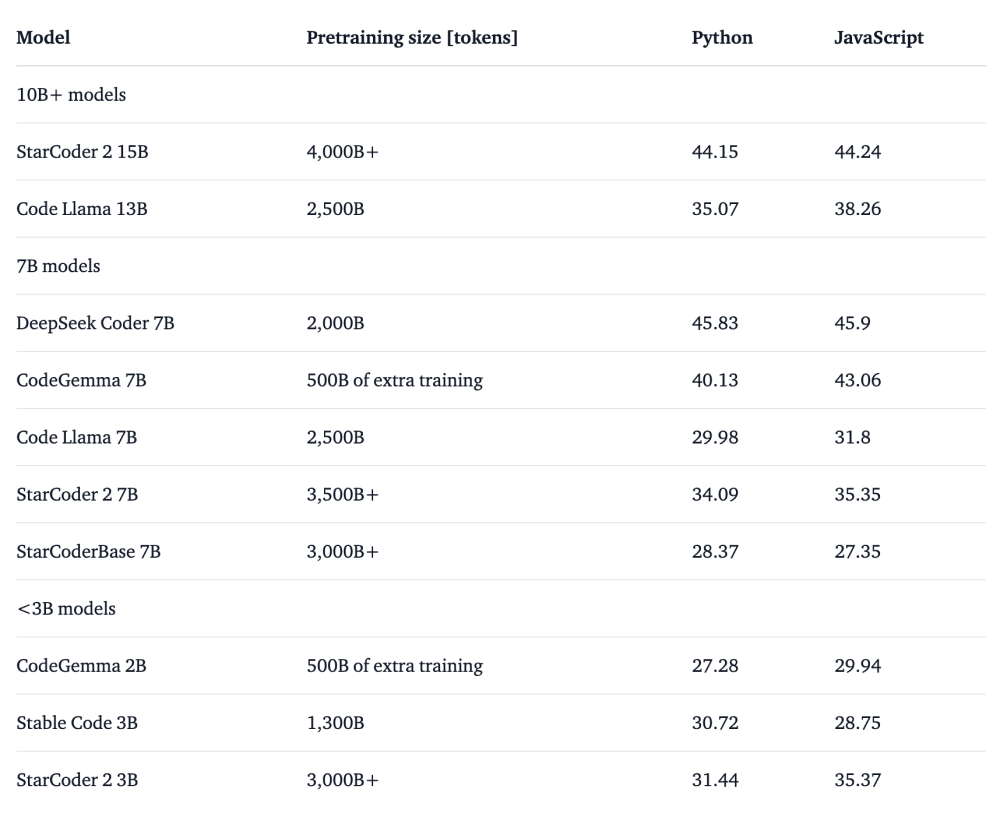
Apart from DeepSeek-Coder-7B, CodeGemma-7B outperforms most comparable 7B models on the HumanEval benchmark, which is widely used to evaluate the performance of Python code models. In addition, CodeGemma-7B also demonstrates excellent performance when evaluating other programming languages such as Java, JavaScript, and C++, based on MultiPL-E, a multilingual extension of the HumanEval benchmark. According to the technical report, CodeGemma-7B performs best on the GSM8K test, ranking first among all 7B models. These performance evaluation results highlight CodeGemma-7B's advanced capabilities in code understanding and generation.