
What is AutoRAG
AutoRAG is a fully managed Retrieval-Augmented Generation (RAG) pipeline launched by Cloudflare, helping developers easily integrate context-aware AI into applications without managing infrastructure. Cloudflare AutoRAG is based on automatically indexing data sources and continuously updating content, combined with Cloudflare's Workers AI, Vectorize, and other technologies, to achieve efficient data retrieval and high-quality AI responses. AutoRAG supports applications such as building support chatbots, internal knowledge tools, and enterprise knowledge search, simplifying the development process, and improving application performance and user experience.
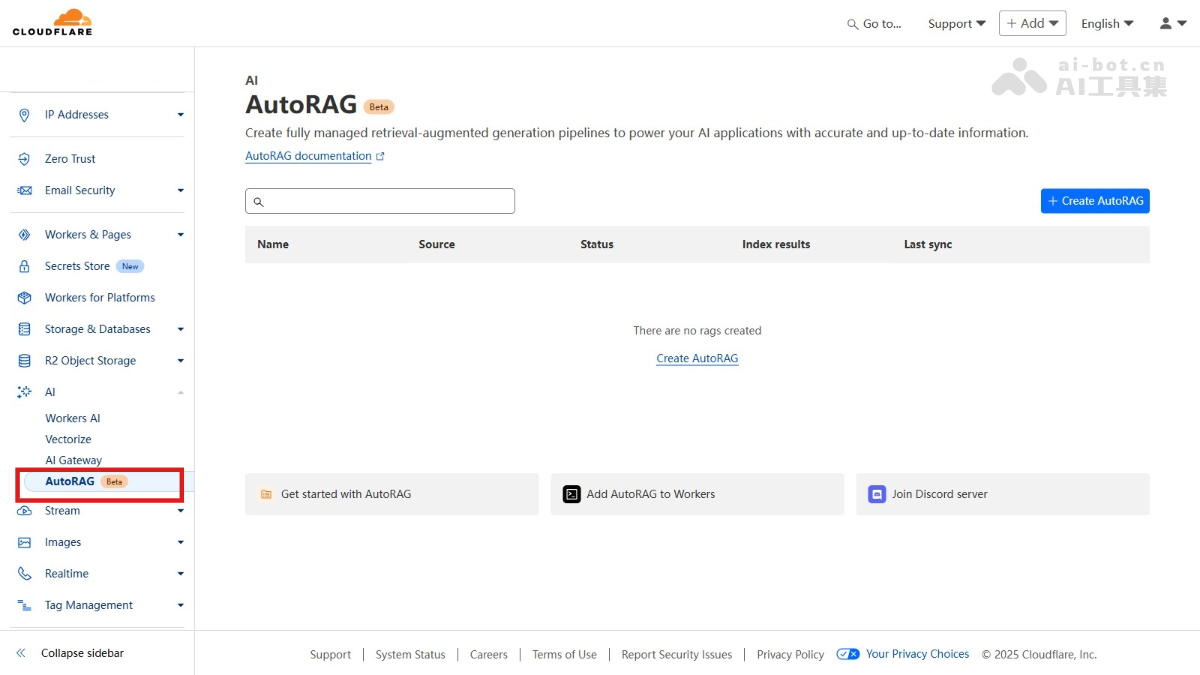
Main Features of AutoRAG
- Automated Indexing: Automatically ingests data from data sources (such as Cloudflare R2 storage buckets). Continuously monitors data sources, automatically re-indexes new or updated files, ensuring content is always up to date.
- Context-Aware Responses: Retrieves relevant information from data sources at query time, combined with user input, to generate accurate responses based on user data.
- High-Performance Semantic Retrieval: Performs efficient semantic search based on a vector database (Cloudflare Vectorize), ensuring rapid retrieval of relevant content.
- Integration and Extensibility: Supports seamless integration with other Cloudflare services (such as Workers AI, AI Gateway). Provides Workers Binding, making it convenient for developers to call AutoRAG directly from Cloudflare Workers.
- Resource Management and Optimization: Provides similarity caching to reduce the computational overhead of repeated queries, optimizing performance. Supports multiple data sources, including parsing content directly from website URLs.
Technical Principles of AutoRAG
- Indexing Process:
- Extract Files from Data Sources: Reads files from specified data sources (such as R2 storage buckets).
- Markdown Conversion: Converts all files into structured Markdown format to ensure consistency.
- Chunking: Splits text content into smaller segments to improve retrieval granularity.
- Embedding Vectorization: The embedding model converts text segments into vectors.
- Vector Storage: Stores vectors and their metadata in Cloudflare's Vectorize database.
- Query Process:
- Receive Query: The user sends a query request based on the AutoRAG API.
- Query Rewriting (Optional): Rewrites the query based on an LLM to improve retrieval quality.
- Vector Transformation: Converts the query into a vector so it can be compared with vectors in the database.
- Vector Search: Searches the Vectorize database for the vectors most relevant to the query vector.
- Content Retrieval: Retrieves the relevant content and metadata from storage.
- Response Generation: The LLM combines the retrieved content and the original query to generate the final response.
AutoRAG Official Website Address
- Official Website Address:cloudflare.AutoRAG
Application Scenarios of AutoRAG
- Support Chatbots: Based on an enterprise knowledge base, provides intelligent Q&A services for customers, improving customer experience.
- Internal Knowledge Assistant: Help employees quickly find internal documents and knowledge, improving work efficiency.
- Enterprise Knowledge Search: Provides semantic search functionality, allowing users to find the most relevant content among large volumes of documents.
- Intelligent Question Answering System: Generates intelligent question-answer pairs for use on FAQ pages or online help centers, providing personalized answers.
- Document Semantic Search: Performs semantic search within enterprise document repositories, helping users quickly find the files they need.