
What is CLEAR
CLEAR is a novel linear attention mechanism launched by the National University of Singapore that can improve the efficiency of pretrained Diffusion Transformers (DiTs) in generating high-resolution images. Based on restricting each query's attention to a local window, CLEAR achieves linear complexity with respect to image resolution and reduces computational cost. Experiments show that after 10K iterations of fine-tuning, CLEAR can reduce attention computation by 99.5% while maintaining performance similar to the original model, and achieves a 6.3x speedup when generating 8K images. CLEAR supports zero-shot generalization across models and plugins, as well as multi-GPU parallel inference, enhancing the model's applicability and scalability.
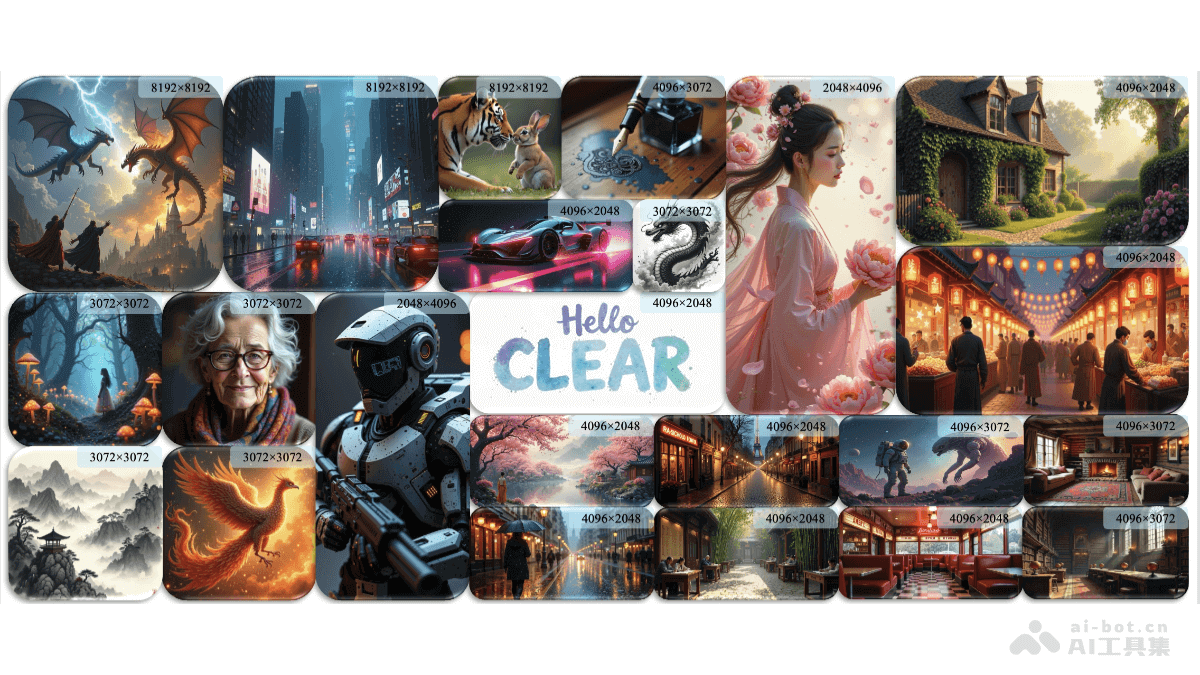
Main Features of CLEAR
- Linear complexity: Through a local attention mechanism, the complexity of pretrained DiTs is reduced from quadratic to linear, making it suitable for high-resolution image generation.
- Efficiency improvement: When generating high-resolution images, it significantly reduces computation and time latency, accelerating the image generation process.
- Knowledge transfer: Through a small amount of fine-tuning, it can effectively transfer knowledge from the pretrained model to the student model while maintaining generation quality.
- Cross-resolution generalization: CLEAR demonstrates good cross-resolution generalization ability and can handle image generation tasks of different sizes.
- Cross-model/plugin generalization: The attention layers trained by CLEAR can generalize zero-shot to other models and plugins without additional adaptation.
- Multi-GPU parallel inference: CLEAR supports multi-GPU parallel inference, optimizing the efficiency and scalability of large-scale image generation.
Technical Principles of CLEAR
- Local attention window: Restricts each query to a local window and interacts only with the key-value pairs within the window, achieving linear complexity.
- Circular window design: Unlike the traditional square sliding window, CLEAR uses a circular window and considers all key-value pairs within the Euclidean distance of each query.
- Knowledge distillation: During fine-tuning, CLEAR uses a knowledge distillation objective based on flow matching loss and prediction/attention output consistency loss to reduce the difference between the linearized model and the original model.
- Multi-GPU parallel inference optimization: Based on the locality of local attention, CLEAR reduces communication overhead during multi-GPU parallel inference and improves the efficiency of large-scale image generation.
- Preserving original functionality: Although each query accesses only local information, by stacking multiple Transformer blocks, each token can gradually capture global information, similar to the operation of convolutional neural networks.
- Sparse attention implementation: As a sparse attention mechanism, it can be efficiently implemented on GPUs and leverages low-level optimizations.
CLEAR Project Address
- GitHub repository:https://github.com/Huage001/CLEAR
- arXiv technical paper:https://arxiv.org/pdf/2412.16112
Application Scenarios of CLEAR
- Digital media creation: Artists and designers can quickly generate high-resolution images and artworks, improving creative efficiency.
- Virtual reality (VR) and augmented reality (AR): In VR and AR applications, it is used to generate high-resolution virtual environments and objects in real time, enhancing the user experience.
- Game development: Game developers generate high-quality game assets and backgrounds, reducing development time and resource consumption.
- Film and Video Production: In film and video production, it is used to generate high-resolution special effects images and animations, improving post-production efficiency.
- Advertising and Marketing: Marketers quickly generate attractive advertising images and visual content to attract potential customers.