
What is ChatAnyone
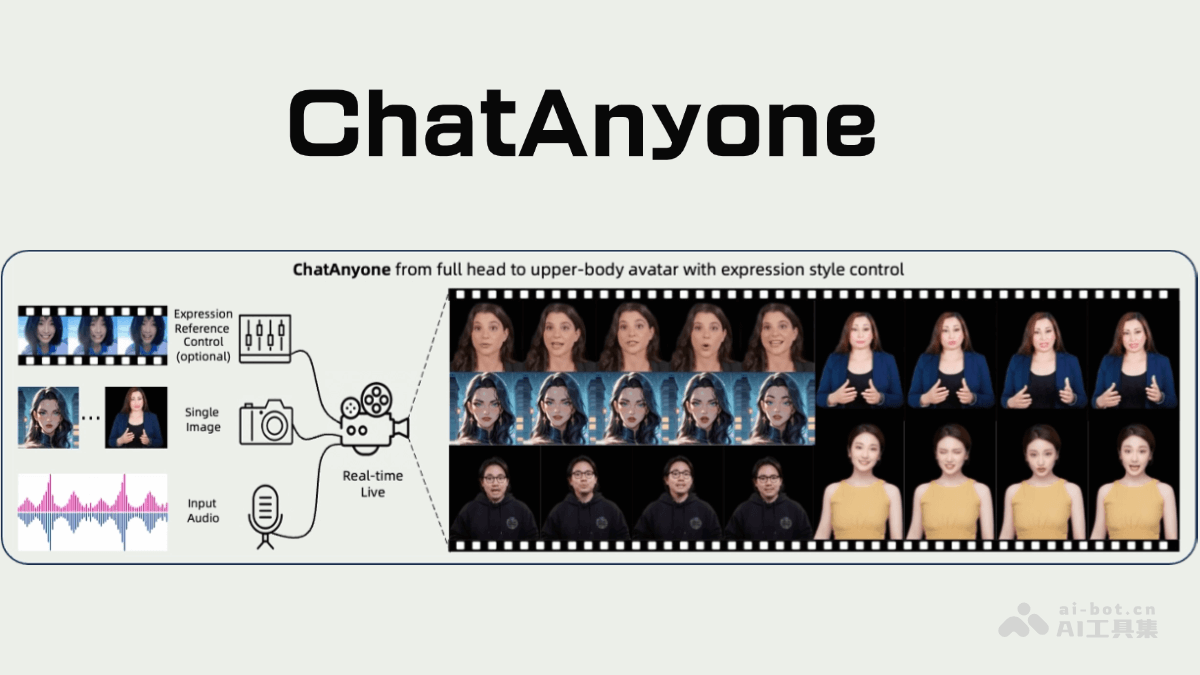
ChatAnyone is a real-time stylized portraitvideo generationframework launched by Alibaba Tongyi Lab. Through audio input, it generates portrait videos with rich expressions and upper-body movements. It adopts an efficient hierarchical motion diffusion model and a hybrid control fusion generation model, enabling high-fidelity and natural video generation, and supports real-time interaction, making it suitable for numerous scenarios such as virtual anchors, video conferencing, content creation, education, customer service, marketing, social entertainment, and healthcare. ChatAnyone supports stylized control, allowing expression styles to be adjusted according to needs to achieve personalized animation generation.
ChatAnyone's Main Features
- Audio-Driven Portrait Video Generation: Through audio input, it generates portrait videos with rich expressions and upper-body movements, achieving high-fidelity animation generation from a "talking head" to upper-body interaction, and supporting diverse facial expressions and style control.
- High Fidelity and Naturalness: The generated portrait videos have rich expressions and natural upper-body movements.
- Real-Time Capability: It supports real-time interaction, making it suitable for application scenarios such as video chat.
- Stylized Control: Expression styles can be adjusted according to needs to achieve personalized animation generation.
ChatAnyone's Technical Principles
- Efficient Hierarchical Motion Diffusion Model: It takes audio signals as input and outputs facial and body control signals, considering both explicit and implicit motion signals. It generates diverse facial expressions and achieves synchronization of head and body movements. It supports expression variations of different intensities, as well as transferring stylized expressions from reference videos.
- Hybrid Control Fusion Generation Model: It combines explicit landmarks and implicit offsets to generate realistic facial expressions. It injects explicit hand control signals to generate more accurate and realistic hand movements. Through the facial optimization module, it enhances facial realism and ensures that the generated portrait videos have a high degree of expressiveness and realism.
- Scalable Real-Time Generation Framework: It supports everything from head-driven animation to upper-body generation including gestures. On a 4090 GPU, it generates upper-body portrait videos in real time at up to 512×768 resolution and 30fps.
ChatAnyone's Project Address
- Project Official Website:https://humanaigc.github.io/chat-anyone/
- Github Repository:https://github.com/HumanAIGC/chat-anyone
- arXiv Technical Paper:https://arxiv.org/pdf/2503.21144
ChatAnyone's Application Scenarios
- Virtual Anchors and Video Conferencing: Used for virtual avatars in news broadcasting, livestream e-commerce, and video conferencing.
- Content Creation and Entertainment: Generate stylized animated characters, virtual concerts, AI podcasts, and more.
- Education and Training: Generate virtual teacher avatars and virtual characters in training simulations.
- Customer Service: Generate virtual customer service avatars to provide vivid answers and interaction.
- Marketing and Advertising: Generate virtual spokesperson avatars and highly interactive advertising content.