
What Is CCI 3.0
CCI 3.0 is a large-scale Chinese internet corpus released by BAAI, containing a 1000GB dataset and a 498GB high-quality subset, CCI 3.0-HQ. Compared with CCI 2.0, this version has nearly doubled in data scale, and the number of data source institutions has increased to more than 20, improving data coverage and representativeness. CCI 3.0 includes more than 268 million web pages, covering news, social media, blogs, and many other fields. CCI 3.0 carefully classifies and labels the raw data, covering more than 10 dimensions such as grammar, syntax, and education level, and selects high-value data.
Main Features of CCI 3.0
- Data Scale and Sources: The data scale of CCI 3.0 reaches 1000GB, including more than 268 million web pages and covering news, social media, blogs, and many other fields. The number of data source institutions has expanded to more than 20, improving data coverage and representativeness.
- Fine-Grained Annotation: CCI 3.0 carefully classifies and labels the raw data, covering more than 10 dimensions such as grammar, syntax, and education level, and selects high-value data.
- High-Quality Subset: CCI 3.0 includes a 498GB high-quality subset, CCI 3.0-HQ, which was obtained by automatically annotating samples based on a 70B model and then training a small-sized quality model, and can better meet the needs of different industries and application scenarios.
- Data Processing Rules: During construction, CCI 3.0 used methods including rule-based filtering (such as keyword filtering and spam filtering), model-based filtering (such as low-quality content filtering), and data deduplication (including deduplication within and between datasets) to ensure data quality and security.
Technical Advantages of CCI 3.0
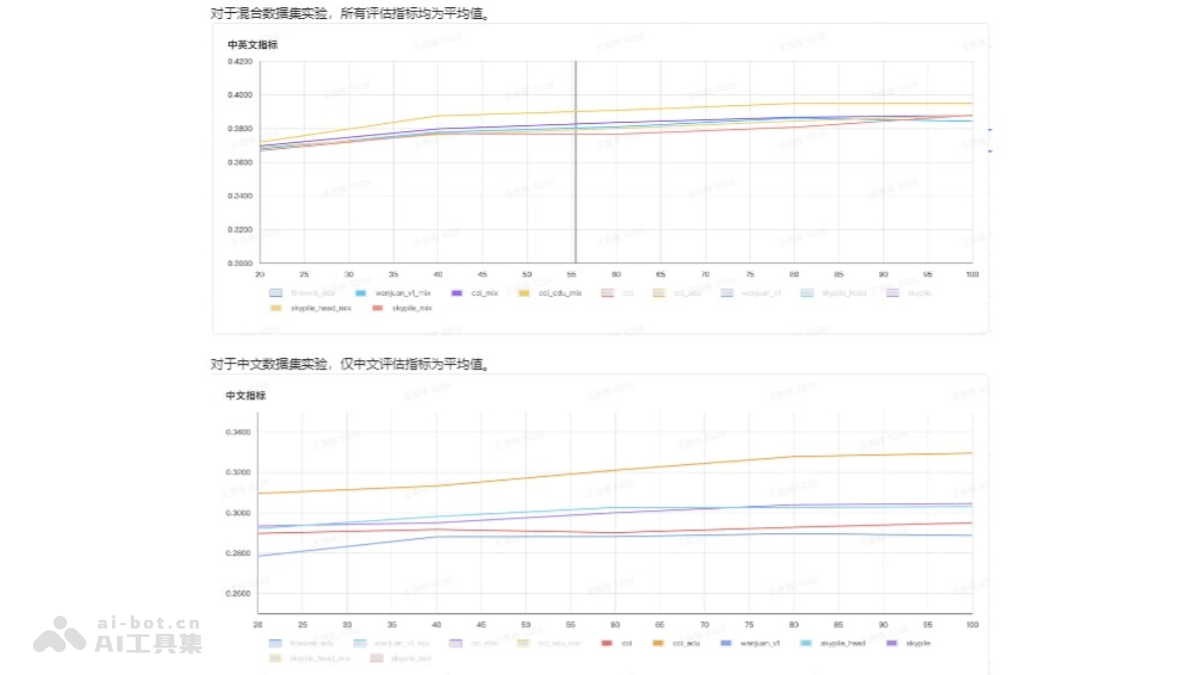
- Significant Training Results: Comparative experiments based on training 100B data from scratch on different datasets show that CCI 3.0 outperforms other datasets in both Chinese-only corpus training and mixed Chinese-English corpus training, and the effect of CCI 3.0 HQ is even more prominent.
- The Concept of Co-Building and Sharing: The release of CCI 3.0 promotes co-building and sharing of data, builds a large-scale, high-quality, high-knowledge-density Chinese dataset, and contributes to the development of China's artificial intelligence industry.
- Convenient Access Methods: The CCI 3.0 dataset can be downloaded on platforms such as Flopsera, Huggingface, and Datahub, making it convenient for researchers and developers to use.
Project Address of CCI 3.0
- Project Official Website:http://open.flopsera.com/flopsera-open/data-details/BAAI-CCI3
Application Scenarios of CCI 3.0
- Natural Language Processing (NLP) Research: CCI 3.0 can be used for various NLP tasks, such as text classification, sentiment analysis, machine translation, question answering systems, and text summarization.
- Large Model Training: The large-scale dataset of CCI 3.0 is suitable for training large language models and improving model performance and accuracy in Chinese contexts.
- Content Recommendation Systems: Based on the corpus data in CCI 3.0, more accurate user behavior prediction models can be trained for personalized content recommendation.
- Knowledge Graph Construction: By analyzing the large amount of text in CCI 3.0, key information can be extracted to build knowledge graphs, which can be used to enhance search engines, enhance the knowledge bases of intelligent assistants, and more.
- Education and Academic Research: CCI 3.0 can serve as a resource for academic research, helping scholars study the characteristics and changing trends of the Chinese language.