
What is Bright Data MCP
Bright Data MCP is a powerful Model Context Protocol (MCP) server designed for public web access. Bright Data MCP enables large language models (LLMs), agents, and applications to access, discover, and extract web data in real time, bypassing geographic restrictions and website anti-scraping mechanisms. The server supports multiple clients, such as Claude Desktop, Cursor, etc., providing seamless integration and optional remote browser automation capabilities. Bright Data MCP is suitable for various application scenarios that require real-time web data support, and is an ideal tool for web scraping and data collection tasks.
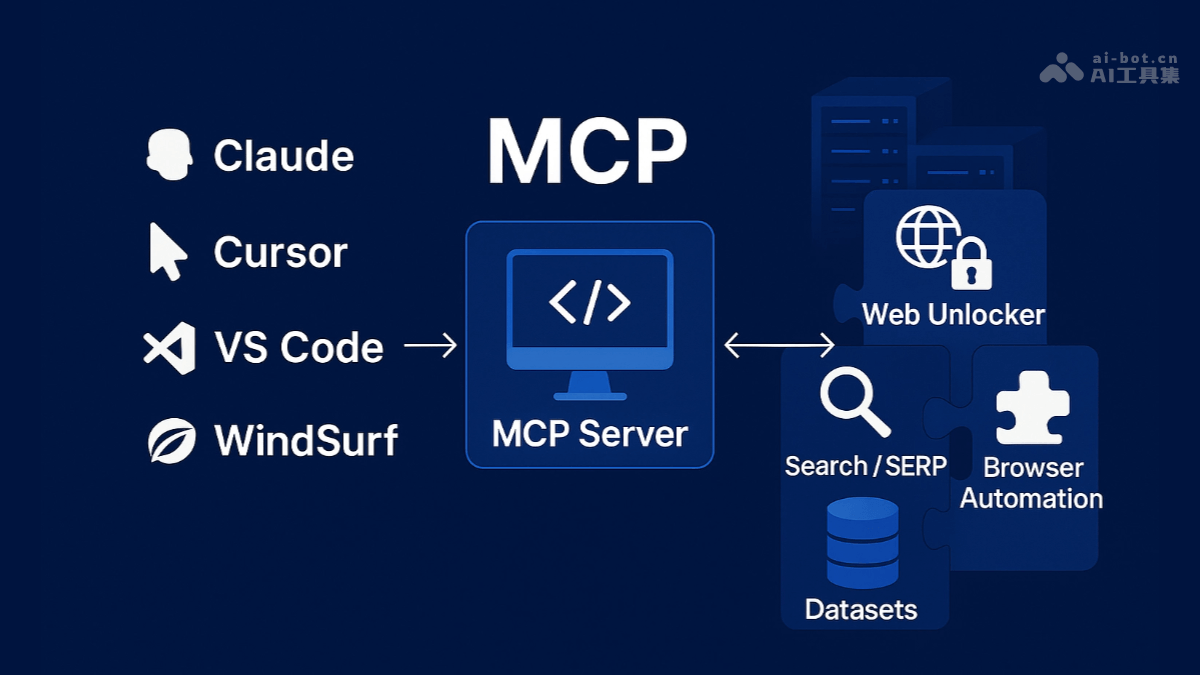
Main Features of Bright Data MCP
- Real-time Web Access: Retrieve the latest information directly from the web, ensuring data timeliness.
- Bypass Geographic Restrictions: Supports accessing content restricted by geographic location, breaking through regional blockades.
- Web Unlocker: Has the ability to bypass website bot detection protection, avoiding being banned.
- Browser Control: Provides optional remote browser automation capabilities, supporting complex web page interactions.
- Seamless Integration: Compatible with all AI assistants and tools that support the MCP protocol, easy to integrate into existing systems.
- Data Security: Emphasizes filtering and validation of scraped content, avoiding potential security risks.
- Flexible Configuration: Supports custom configurations, such as setting API tokens, Agent regions, etc., meeting the needs of different users.
Technical Principles of Bright Data MCP
- Model Context Protocol (MCP): MCP is a protocol that connects AI models with external data sources. Bright Data MCP is based on the MCP protocol, providing AI models with real-time web data access capabilities, allowing models to dynamically obtain the latest information. MCP defines the format of data requests and responses, ensuring efficient and secure data transmission.
- Agent Network and Web Unlocker: Uses the Agent network to bypass geographic restrictions, accessing restricted content through Agent servers distributed in different geographic locations. Web Unlocker technology can identify and bypass website anti-scraping mechanisms, ensuring the stability of data collection.
- Browser Automation: Based on integrated browser automation tools (such as Puppeteer or Selenium), simulates real user behavior to access complex dynamic web pages. Supports remote browser control to achieve more complex interactive operations.
- Data Security and Validation: During data transmission and processing, uses encryption and validation mechanisms to ensure data security. Provides data filtering and validation tools to prevent malicious data injection.
- API-driven Architecture: Communicates with clients based on API interfaces, supporting access from multiple programming languages and tools. Users configure environment variables (such as API tokens) to manage and authenticate data requests.
- Distributed Processing: A distributed architecture handles large volumes of data requests, improving system scalability and performance. Supports multithreading and asynchronous processing, optimizing data collection efficiency.
Project Address of Bright Data MCP
- GitHub Repository:https://github.com/luminati-io/brightdata-mcp
Application Scenarios of Bright Data MCP
- Real-time Information Query: Obtain the latest news, weather, stock quotes, etc.
- Market Research: Analyze competitors, consumer behavior, and industry trends.
- Content Creation: Provide creators with reference materials and creative inspiration.
- Data Scraping: Automatically collect web page data, supporting batch information collection.
- Intelligent Assistant Enhancement: Provide AI assistants with real-time data support to improve their response capabilities.