
What is AnyI2V
AnyI2V is an innovative image animation generation framework jointly launched by Fudan University, Alibaba DAMO Academy, and Hupan Lab. The framework requires no large amount of training data, can transform static conditional images (such as meshes, point clouds, etc.) into dynamic videos, and supports user-defined motion trajectories. AnyI2V supports multiple modal inputs and can be flexibly edited through LoRA and text prompts. The framework performs excellently in spatial and motion control, providing an efficient and flexible new method for image animation.
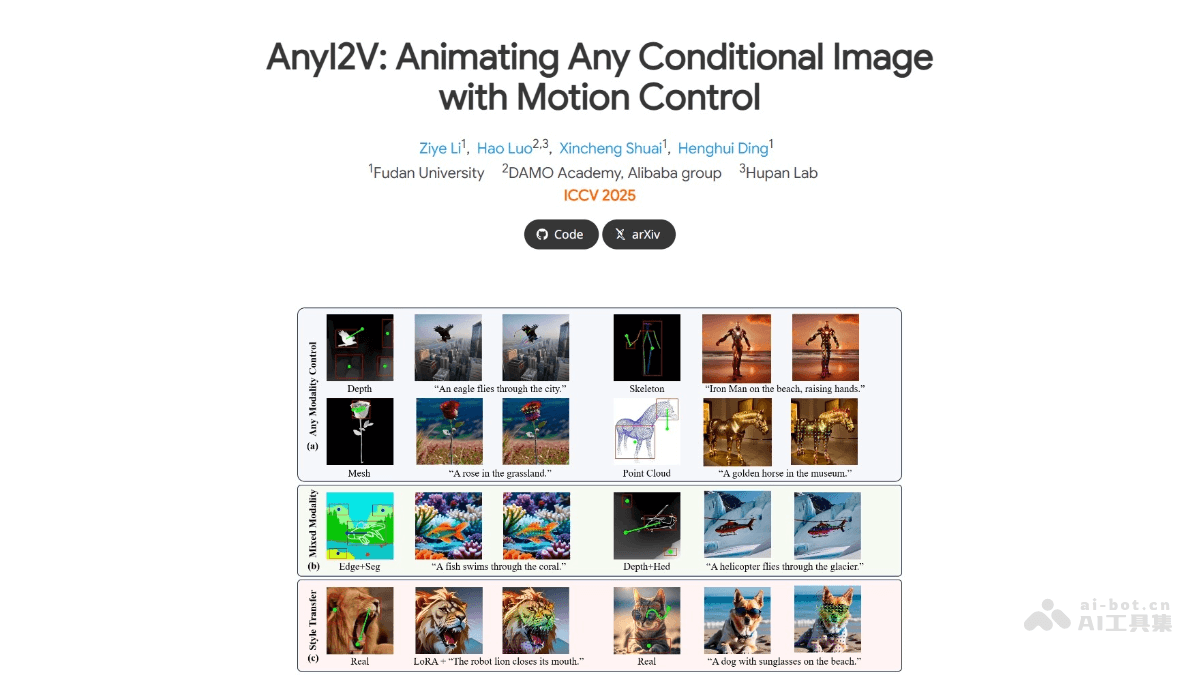
Main features of AnyI2V
- Multimodal support: Supports multiple types of conditional inputs, including modalities such as meshes and point clouds for which paired training data is difficult to obtain.
- Mixed conditional inputs: The framework can accept combinations of different types of conditional inputs, further increasing the flexibility of input.
- Editing function: Through LoRA or different text prompts, the original image can be edited to achieve style transfer and content adjustment.
- Motion control: Supports users in controlling the animation effect of the video by defining motion trajectories, achieving precise motion control.
- No training required: No large amount of training data or complex training process is required, lowering the threshold for use.
Technical principles of AnyI2V
- DDIM inversion: AnyI2V performs DDIM (Denoising Diffusion Implicit Model) inversion on the conditional image. DDIM is a diffusion model that restores an image by gradually removing noise. During the inversion process, AnyI2V extracts features from the conditional image, which will be used in subsequent animation generation.
- Feature extraction and replacement: When extracting features, AnyI2V removes the temporal module (temporal self-attention) in the 3D U-Net. The module is mainly used to process temporal information in videos, while the conditional image only has spatial information. Features are extracted from the spatial blocks of the 3D U-Net and saved at specific time steps.
- Optimizing the latent representation: AnyI2V replaces the extracted features back into the 3D U-Net to optimize the latent representation. Constraints are applied through automatically generated semantic masks to ensure that optimization is performed only in specific regions. The semantic masks are dynamically generated according to the content of the conditional image, improving the accuracy of the generation effect.
- Motion control: Users control the generation of the animation by defining motion trajectories. AnyI2V takes the motion trajectories as input and combines them with the optimized latent representation to generate a video that conforms to the user-defined motion. The motion control mechanism enables users to precisely control the motion paths of objects in the video.
AnyI2V project address
- Project official website:https://henghuiding.com/AnyI2V/
- GitHub repository:https://github.com/FudanCVL/AnyI2V
- arXiv technical paper:https://arxiv.org/pdf/2507.02857
Application scenarios of AnyI2V
- Animation production: Animators can quickly generate animation prototypes and directly transform static images into dynamic videos, providing more creative space for animation creation.
- Video special effects: In film and television production, it is used to generate complex visual effects, transform static scene images into dynamic backgrounds, or add dynamic effects to characters, enhancing visual impact.
- Game development: Game developers can generate dynamic scenes and character animations in games, bringing richer and more vivid visual effects to games.
- Dynamic advertising: Advertising designers can transform static advertising images into dynamic videos to attract viewers' attention.
- Social media content: Brands and content creators generate compelling social media videos, improving content dissemination and user engagement.