
What is AnyCharV
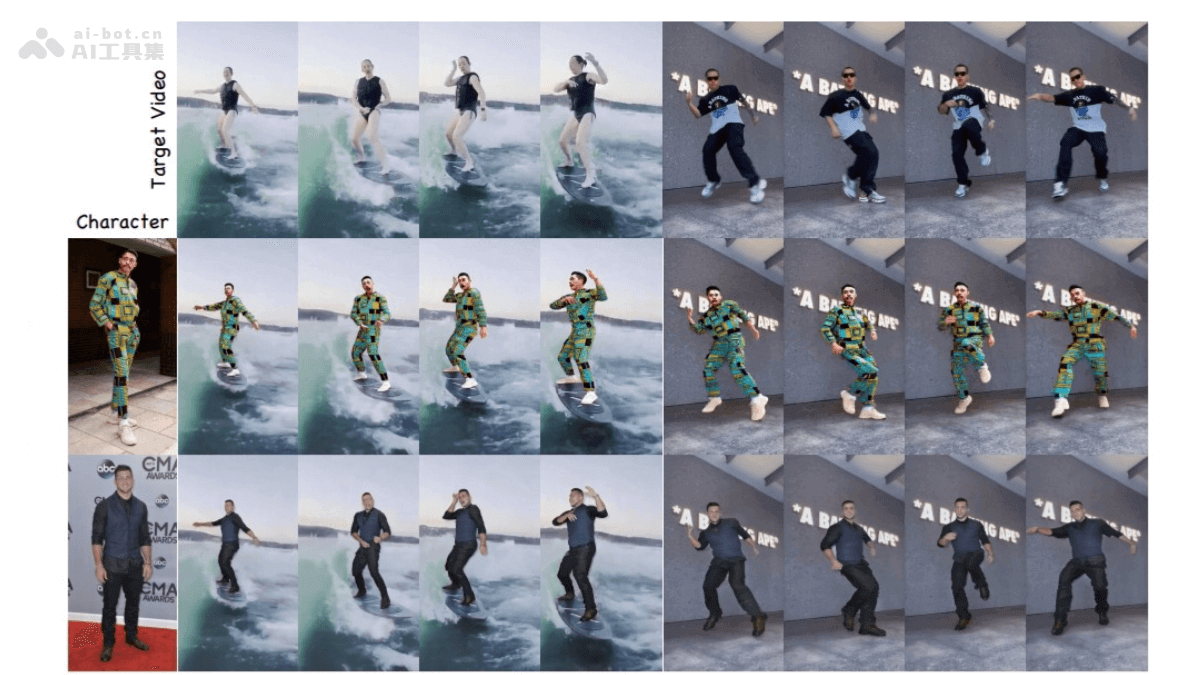
AnyCharV is a character-controllable framework jointly launched by The Chinese University of Hong Kong, Tsinghua University Shenzhen International Graduate School, and The University of Hong Kong.video generationIt can combine any reference character image with a target driving video to generate high-quality character videos. AnyCharV achieves fine-to-coarse guidance based on a two-stage training strategy: the first stage uses fine-grained segmentation masks and pose information for self-supervised synthesis; the second stage uses self-reinforcement training and coarse-grained masks to optimize character detail preservation. AnyCharV demonstrates superior performance in experiments, can naturally preserve the character's appearance details, and supports complex human-object interaction and background fusion. AnyCharV can work withtext-to-image(T2I) andtext-to-video(T2V) model-generated content, and has strong generalization ability.
Main features of AnyCharV
- Synthesis of arbitrary characters with target scenes: Combine any given character image with a target driving video to generate natural, high-quality videos.
- High-fidelity character detail preservation: Based on self-reinforcement training and coarse-grained mask guidance, preserve the character's appearance and details and avoid distortion.
- Complex scenes and human-object interaction: Support natural interaction of characters in complex backgrounds, such as movement and object manipulation.
- Flexible input support: Combine content generated by text-to-image (T2I) and text-to-video (T2V) models, with strong generalization ability.
Technical principles of AnyCharV
- First stage: Self-supervised synthesis and fine-grained guidance: Use the segmentation mask and pose information of the target character as conditional signals to accurately synthesize the reference character into the target scene. Introduce the CLIP features of the reference image and the character appearance features extracted by ReferenceNet to preserve the character's identity and appearance. Apply strong augmentation to the segmentation mask to reduce detail loss caused by shape differences.
- Second stage: Self-reinforcement training and coarse-grained guidance are based on generated video pairs for self-reinforcement training, replacing fine segmentation masks with coarse bounding box masks to reduce constraints on character shape. Based on this approach, the model can better preserve the details of the reference character and generate more natural videos during inference.
Project address of AnyCharV
- Project official website:https://anycharv.github.io/
- GitHub repository:https://github.com/AnyCharV/AnyCharV
- arXiv technical paper:https://arxiv.org/pdf/2502.08189
Application scenarios of AnyCharV
- Film and television production: Synthesize arbitrary characters into target scenes, support complex interactions, and assist special effects production.
- Artistic creation: Combine text-generated content to quickly generate high-quality character videos and inspire creativity.
- Virtual reality: Generate interaction videos between characters and virtual scenes in real time to enhance immersion.
- Advertising and marketing: Quickly synthesize personalized advertising videos to meet diverse needs.
- Education and training: Generate videos of specific characters and scenes to assist teaching and training.