
What Is AntSK FileChunk
AntSK FileChunk is an intelligent text chunking tool based on semantic understanding, specifically designed for processing PDF and Word documents. The tool is based on advanced semantic analysis technology, dividing long documents into semantically complete and coherent segments to avoid the semantic fragmentation caused by traditional methods. AntSK FileChunk supports multiple document formats and features powerful capabilities such as intelligent document parsing, adaptive chunking, and multilingual processing. AntSK FileChunk provides a web interface, command-line tool, and HTTP API, making it easy to use and integrate, and is the ideal choice for processing long documents.
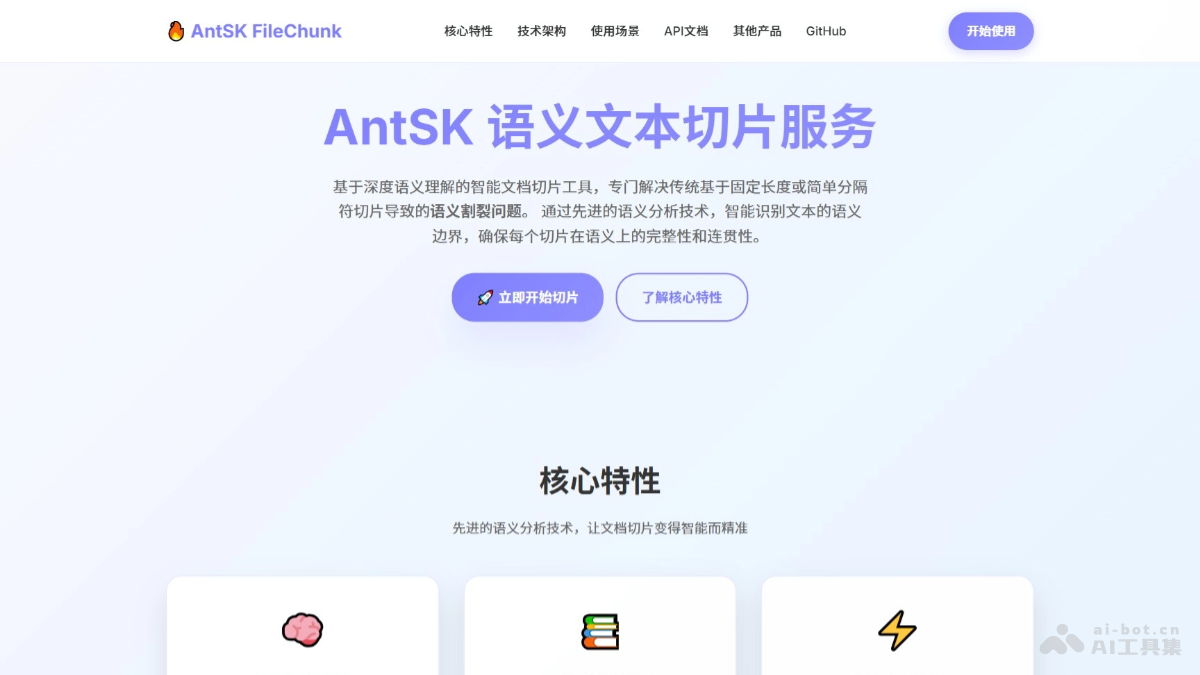
Main Features of AntSK FileChunk
- Semantic-Aware Chunking: Semantic understanding is performed through Transformer models to ensure the reasonableness of chunk boundaries and avoid the semantic fragmentation caused by traditional splitting methods.
- Multi-Format Support: Supports multiple document formats such as PDF, Word (.docx/.doc), and plain text, meeting the needs of different scenarios.
- Intelligent Document Parsing: Automatically identifies and processes special content such as document structures, tables, and images, maintaining the integrity and coherence of documents.
- Adaptive Chunking: Dynamically adjusts chunk size according to content characteristics, balancing semantic integrity and processing efficiency.
- Multilingual Support: Supports Chinese and English document processing, adapting to different language environments.
Technical Principles of AntSK FileChunk
- Document Parsing: Uses tools such as PyMuPDF and python-docx to extract structured information such as paragraphs, tables, and images from documents. Cleans noise and standardizes formats to prepare for subsequent processing.
- Text Preprocessing: Performs segmentation processing on the extracted text to ensure the independence of each paragraph. Cleans noise such as extra spaces and line breaks in the text.
- Semantic Analysis: Uses Transformer models (such as sentence-transformers) to calculate semantic vectors of paragraphs. Calculates similarity between paragraphs through semantic vectors to identify semantic boundaries.
- Intelligent Chunking: Based on semantic thresholds and length constraints, divides documents into semantically complete segments. Dynamically adjusts chunk size to ensure the semantic completeness and coherence of each chunk.
AntSK FileChunk Project Address
- Project Website:https://filechunk.antsk.cn/
- GitHub Repository:https://github.com/xuzeyu91/AntSK-FileChunk
Application Scenarios of AntSK FileChunk
- Content Management Systems (CMS): Divides long documents into semantically complete segments, facilitating chunked storage and fast retrieval in content management systems, improving content readability and user experience.
- Knowledge Graph Construction: Through semantic-aware chunking, divides long documents into segments with clear semantic boundaries, facilitating the extraction of key information to construct knowledge graphs and improving their accuracy and completeness.
- Intelligent Customer Service Systems: Divides long documents into small semantic segments, facilitating intelligent customer service systems to quickly locate and extract relevant information, improving the accuracy and efficiency of responses.
- Academic Research: Divides academic papers into semantically complete segments, facilitating researchers to quickly browse and extract key information, improving research efficiency and quality.
- Enterprise Internal Knowledge Management: Divides long enterprise internal documents into small semantic segments, facilitating team members to quickly find and use the required information, improving the efficiency and effectiveness of enterprise internal knowledge management.