
What is AnimateDiff?
AnimateDiff is a framework launched by researchers from Shanghai AI Laboratory, The Chinese University of Hong Kong, and Stanford University that extends personalized text-to-image models into animation generators. Its core lies in its ability to leverage motion priors learned from large-scale video datasets, and it can serve as a plug-in for the Stable Diffusion text-to-image model, allowing users to convert static images into dynamic animations. The purpose of this framework is to simplify the animation generation process, enabling users to control the content and style of animations through text descriptions without the need for specific model tuning.
AnimateDiff official website entry
- Official project homepage:https://animatediff.github.io/
- Arxiv research paper:https://arxiv.org/abs/2307.04725
- GitHub code repository:https://github.com/guoyww/animatediff/
- Hugging Face Demo:https://huggingface.co/spaces/guoyww/AnimateDiff
- OpenXLab Demo:https://openxlab.org.cn/apps/detail/Masbfca/AnimateDiff
AnimateDiff features
- Personalized animation generation: AnimateDiff allows users to convert personalized text-to-image models (such as Stable Diffusion) into animation generators. This means that users can input text descriptions, and the model can not only generate static images but also generate animation sequences that match the text descriptions.
- No model-specific adjustments required: The core advantage of AnimateDiff is that it does not require additional adjustments to personalized models. Users can directly use the pretrained motion modeling module in the framework and insert it into a personalized T2I model to achieve animation generation.
- Preserve style characteristics: During the animation generation process, AnimateDiff can preserve the domain characteristics of the personalized model, ensuring that the generated animation content remains consistent with the user's customized style and theme.
- Cross-domain applications: AnimateDiff supports personalized models in multiple domains, including anime, 2D cartoons, 3D animation, and realistic photography, allowing users to freely switch between different styles and themes and create diverse animation content.
- Easy to integrate: AnimateDiff is designed to be easy to integrate with existing personalized T2I models. Users do not need a deep technical background to use it, greatly lowering the barrier to use.
How AnimateDiff works
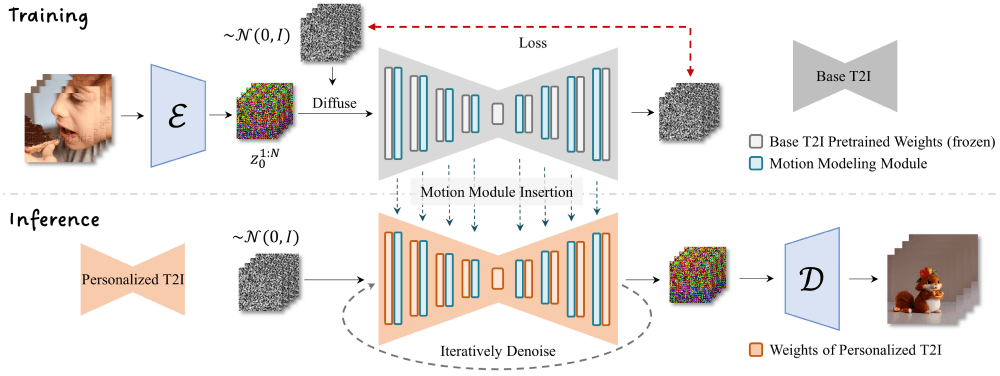
- Insertion of the motion modeling module: First, AnimateDiff inserts a specially designed motion modeling module into an existing text-to-image model. This module is responsible for understanding and generating motion information in animations, and it is designed to work at different resolution levels of the model to ensure that the generated animation remains consistent in details.
- Video data training: The motion modeling module learns motion patterns in videos by training on large-scale video datasets. This training process is carried out while the model is frozen, that is, the parameters of the base T2I model remain unchanged to avoid affecting its original image generation capability.
- Attention mechanism in the temporal dimension: AnimateDiff uses standard attention mechanisms (such as self-attention in Transformer) to handle the temporal dimension. This mechanism allows the model, when generating each frame of an animation, to take into account the information from the previous frame and the next frame, thereby achieving smooth transitions and coherent actions.
- Animation generation: Once the motion modeling module has finished training, it can be inserted into any personalized model based on the same underlying text-to-image model. When generating animations, the user inputs a text description, and the model combines the text content with the motion prior knowledge learned by the motion modeling module to generate an animation sequence that matches the text description.