
What is AnchorCrafter
AnchorCrafter is an intelligent video production system based on diffusion models, used to automatically generate high-fidelity anchor-style product promotion videos. Based on integrating human-object interaction (HOI) into pose-guided human video generation, it achieves a high degree of restoration of object appearance and motion control, as well as management of complex human-object interactions. The system adopts HOI-appearance perception and HOI-motion injection technologies, as well as the HOI-region reweighting loss training objective, to enhance the learning of object details and ensure consistency of human appearance and actions during video generation. AnchorCrafter outperforms existing methods in object appearance preservation, interaction perception, and video quality, providing new possibilities for online advertising and consumer engagement.
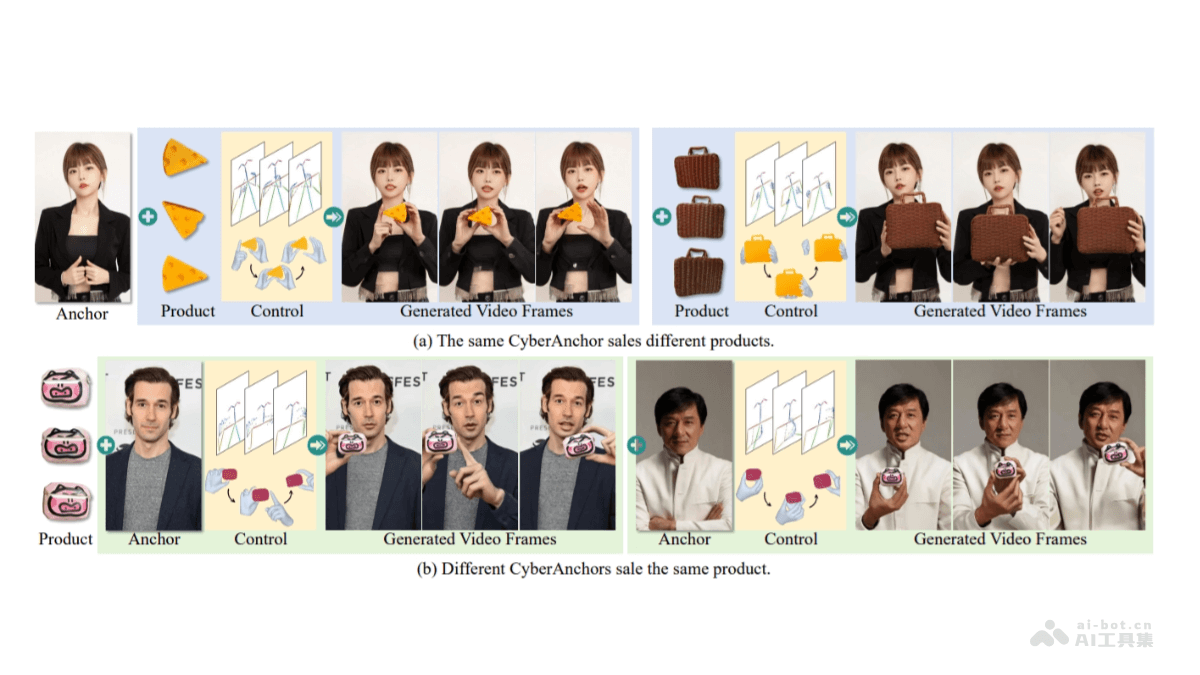
Main features of AnchorCrafter
- High-quality video generation: Automatically create high-fidelity anchor-style product promotion videos.
- Human-object interaction (HOI) integration: Naturally integrate human-object interaction into videos, improving the realism and interactivity of the videos.
- Appearance preservation: Preserve the appearance details of objects in videos, ensuring that the object's appearance is accurate when observed from multiple viewpoints.
- Motion control: Precisely control the object's motion trajectory, coordinating consistently with human actions.
- Mutual occlusion management: Handle occlusion issues during human-object interaction, maintaining the coherence and naturalness of the video.
- Detail-enhanced learning: Enhance the learning of object details during training based on HOI-region reweighting loss.
Technical principles of AnchorCrafter
- Video diffusion model: Based on a diffusion model architecture, it uses a diffusion UNet and variational autoencoder (VAE) to process video frames, encode video sequences into latent space, and reconstruct high-quality video frames from noise.
- HOI-appearance perception:
- Multi-view feature fusion: Use multi-view object reference images to extract object appearance features, enhancing the model's ability to recognize object shapes and textures.
- Human-object dual adapter: Based on replacing the cross-attention layers in the UNet, it achieves better separation of human and object features and avoids appearance entanglement.
- HOI-motion injection:
- Object trajectory control: Use depth maps as input and process depth information based on a lightweight convolutional network to control the motion trajectory of objects in the video.
- Mutual occlusion handling: Combine 3D hand mesh input to handle occlusion issues during interaction between human hands and objects, ensuring the naturalness and accuracy of the interaction.
- HOI-region reweighting loss: During training, increase the weight of hand-object interaction regions, making the model pay more attention to these regions and improving the learning and generation quality of object details.
AnchorCrafter project address
- Project official website:cangcz.github.io/Anchor-Crafter
- GitHub repository:https://github.com/cangcz/AnchorCrafter(coming soon)
- arXiv technical paper:https://arxiv.org/pdf/2411.17383
Application scenarios of AnchorCrafter
- Online shopping platforms: Automatically generate product introduction videos, enhancing the attractiveness of product pages and users' willingness to purchase.
- Social Media Marketing: Provide tools for brands and individual creators to produce engaging product promotional content, increase fan interaction and brand exposure.
- TV Commercial Production: Quickly produce high-quality TV commercials, reducing traditional filming costs and time.
- Virtual Livestream Selling: Use virtual hosts in livestreams to display and promote products, improving livestream efficiency and viewer experience.
- Education and Training: Produce instructional videos that simulate actual operating processes, such as cooking, handicrafts, etc., enhancing learning outcomes.