
What is Amphion
Amphion is an open-source audio, music, and speech generation toolkit, jointly launched by the team of Associate Professor Wu Zhizheng from The Chinese University of Hong Kong, Shenzhen, together with Shanghai AI Laboratory and Shenzhen Research Institute of Big Data. The toolkit supports reproducible research and helps junior researchers and engineers quickly enter the field of audio, music, and speech generation. Amphion provides a variety of functions, including text-to-speech (TTS), singing voice synthesis (SVS), voice conversion (VC), singing voice conversion (SVC), text-to-audio (TTA), and text-to-music (TTM). It integrates a variety of neural vocoders, such as MelGAN, HiFi-GAN, etc., and comprehensive evaluation metrics to ensure the quality and consistency of generated audio. The unique aspect of Amphion lies in the visualization function of classic models and architectures, which helps researchers and engineers deeply understand the internal working principles of the models.
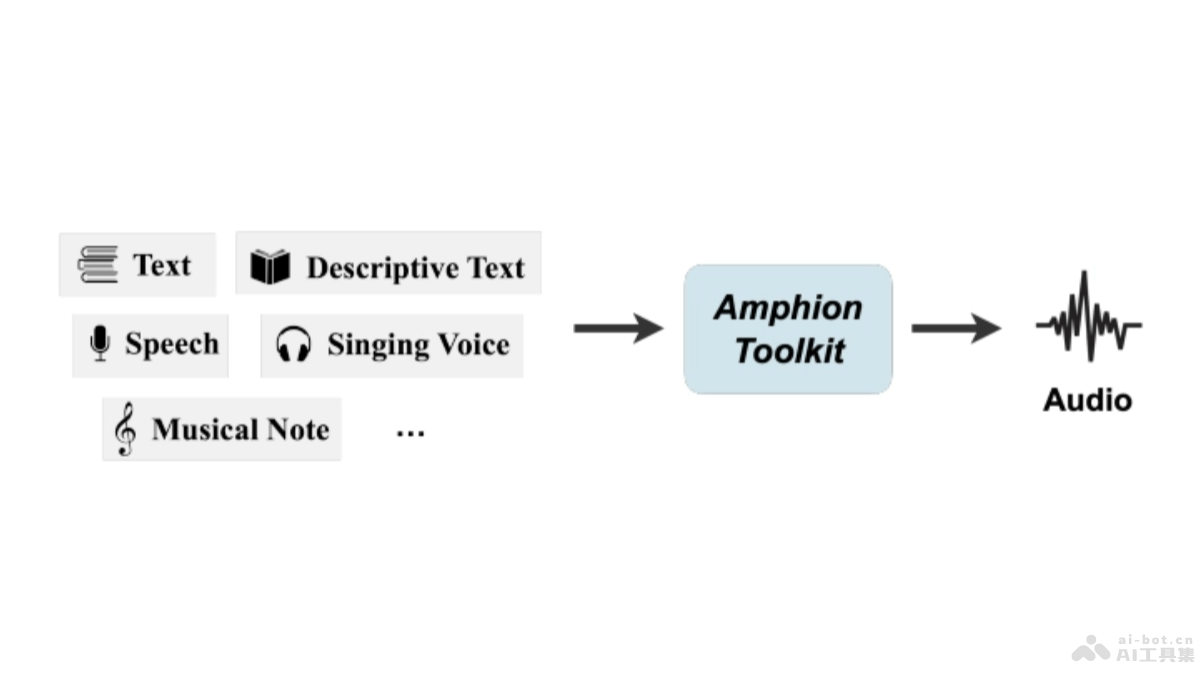
Main Features of Amphion
- Text-to-Speech (TTS): Amphion supports a variety of advanced TTS models and can convert text into natural and fluent speech output.
- Singing Voice Synthesis (SVS): Based on extracting relevant features from reference and source audio, Amphion can synthesize singing voices and achieve conversion of the singer's voice.
- Voice Conversion (VC): Amphion can convert one person's voice into another person's voice without changing the speech content.
- Singing Voice Conversion (SVC): Amphion can convert one singer's singing voice into another singer's singing voice.
- Text-to-Audio (TTA): Amphion can generate realistic sound effects, speech, and music based on text prompts.
- Text-to-Music (TTM): Amphion can convert text descriptions into musical works.
- Vocoder: Amphion integrates a variety of vocoders for generating high-quality audio signals.
Technical Principles of Amphion
- Model Architecture Visualization: Amphion provides visualization of classic models or architectures, helping researchers and engineers better understand the working principles of the models.
- Unified Framework: Amphion provides a unified framework that supports a variety of audio generation tasks, making research and development more convenient.
- Pretrained Models: Amphion releases a variety of high-quality pretrained models to promote reproducible research.
- Neural Vocoder Integration: Amphion integrates a variety of neural vocoders, such as GAN-based vocoders (MelGAN, HiFi-GAN, etc.), flow-based vocoders (WaveGlow), and diffusion-based vocoders (DiffWave).
- Text-to-Audio Generation: Amphion uses latent diffusion models, similar to the designs of AudioLDM, Make-an-Audio, and AUDIT, to generate audio based on text prompts.
Project Address of Amphion
- Project Official Website:openhlt.github.io/amphion
- GitHub Repository:https://github.com/open-mmlab/amphion
- HuggingFace Model Library:https://huggingface.co/amphion
- arXiv Technical Paper:https://arxiv.org/pdf/2312.09911
Application Scenarios of Amphion
- Intelligent Voice Assistant: Amphion can develop more natural and more personalized speech synthesis systems, improving the user experience of intelligent voice assistants.
- Virtual Anchors and Virtual Avatars: Use Amphion's TTS and SVS functions to create virtual anchors for news broadcasting, online education, entertainment livestreaming, and more.
- Music Production: Music producers use Amphion to generate unique sound effects and music clips, sparking creative inspiration and accelerating the music creation process.
- Film and game voiceover: In film production and game development, Amphion creates or alters characters' voices to suit different scenes and character settings.
- Speech recognition and interaction systems: Amphion is used in developing and improving speech recognition systems, making them more accurate and natural.