
What is AMD-135M
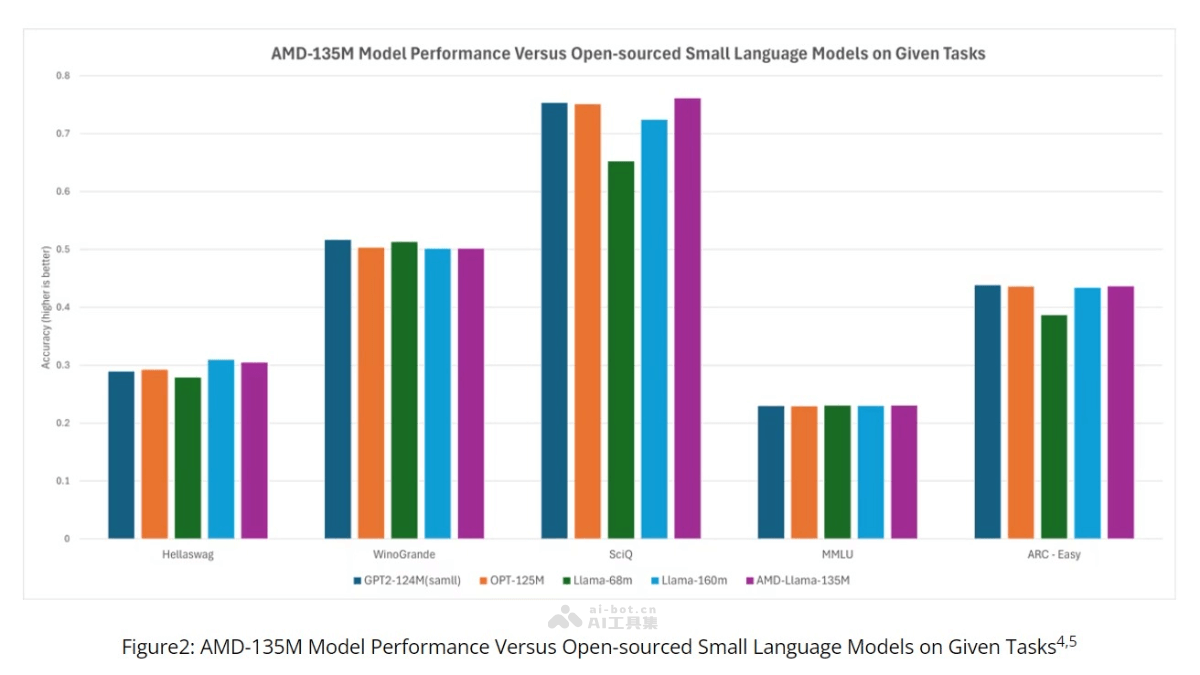
AMD-135M is AMD's first small language model (SLM), providing a balance between performance and resource consumption for specific use cases. Based on the LLaMA2 model architecture and trained on AMD Instinct MI250 accelerators with 67 billion tokens, AMD-135M is available in two versions: AMD-Llama-135M for general text and AMD-Llama-135M-code for code. AMD-135M uses speculative decoding technology to generate multiple tokens in each forward pass, improving inference speed and reducing memory usage. In terms of performance, AMD-135M performs comparably to other similar models on the market across various natural language processing tasks. For example, when using the MI250 GPU on the Humaneval dataset, it achieves a pass rate of approximately 32.31%, which is a strong performance indicator.
Main features of AMD-135M
- Text generation: Can generate coherent text, supporting applications such as chatbots and content creation.
- Code generation: Based on the fine-tuned version AMD-Llama-135M-code, supports code generation and programming assistance.
- Natural language understanding: Understands the intent and context of input text, used for question-answering systems, summary generation, etc.
- Multi-platform compatibility: Runs on different hardware platforms, including AMD GPUs and CPUs.
Technical principles of AMD-135M
- Speculative decoding: Generates candidate tokens through a small draft model, which are then verified by a large target model, improving inference efficiency.
- Autoregressive method: The traditional generation method generates one token per forward pass, but is optimized through speculative decoding technology.
- Multi-head attention mechanism: Uses a multi-head attention mechanism to improve the model's ability to capture relationships between different parts of the text.
- Positional encoding: Uses relative position encoding (RoPE) to preserve the order information of words in a sequence.
- Activation function: Uses the Swiglu activation function, which is an activation function designed specifically for language models.
- Layer Norm: Uses RMSNorm (Root Mean Square Normalization) to stabilize the training process.
- Model architecture: Based on the LLaMA-2 model architecture, with 12 layers, 768 hidden units, and other technical specifications.
Project address of AMD-135M
- Project official website:amd-first-slm-135m-model-fuels-ai-advancements
- HuggingFace model repository:https://huggingface.co/amd/AMD-Llama-135m
Application scenarios of AMD-135M
- Chatbots: As the backend of a chatbot, provides natural language understanding and generation capabilities to enable interactive dialogue with users.
- Content creation: Assists writing, generating drafts of articles, stories, or other text content.
- Programming assistance: Based on the AMD-Llama-135M-code version, helps developers generate code snippets, provides programming suggestions, and auto-completion.
- Language translation: The model is mainly targeted at English, but the architecture adapts to other languages for machine translation tasks.
- Text summarization: Automatically generates summaries of text, used for quick overviews of news, articles, or reports.