
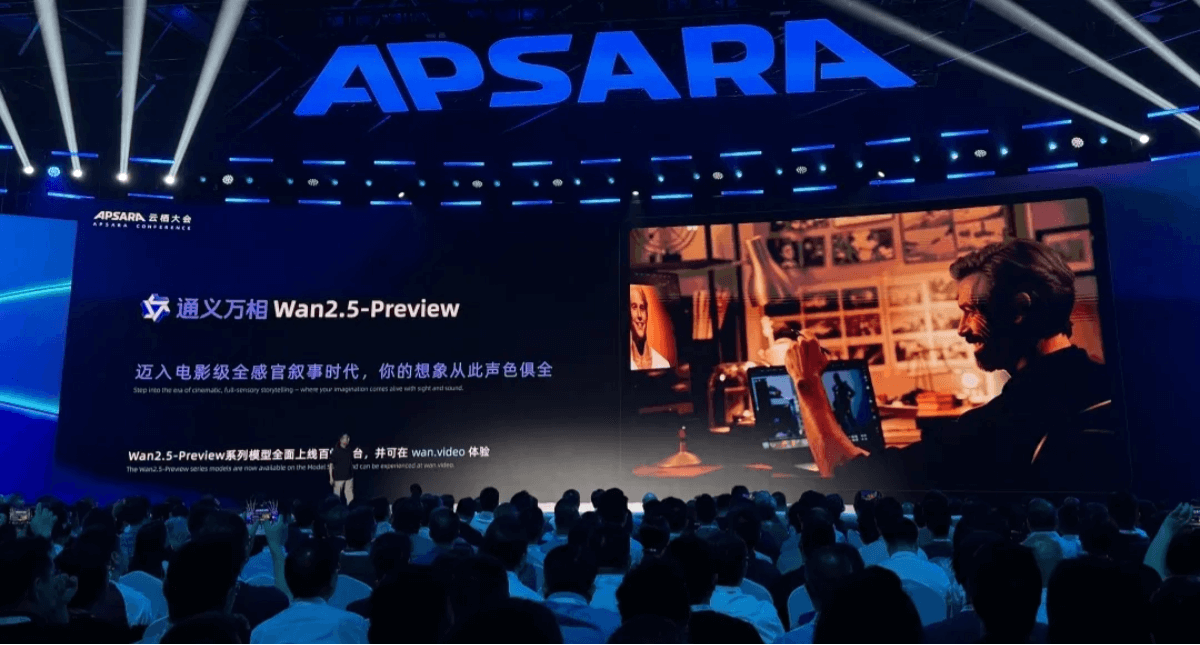
2025 Apsara ConferenceIt's finally here! This year's theme is "Cloud-Intelligence Integration • Silicon-Carbon Symbiosis," with more than 2,000 speakers from over 50 countries around the world gathering in Hangzhou to hold dialogues on cutting-edge topics such as Agentic AI and Physical AI. The scene can be called a tech Spring Festival Gala.
What drew the most attention this morning was still Alibaba's latest large model—Tongyi Wanxiang Wan2.5-Preview series models。
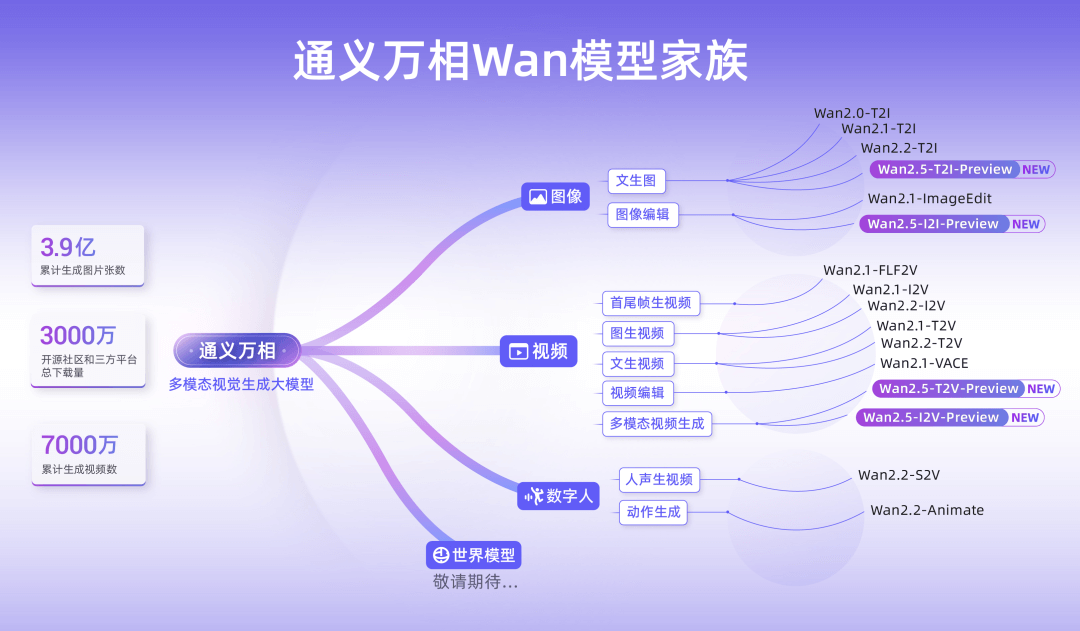
The Wan2.5-Preview series models aremulti-sensory storytelling, adopting a native multimodal architecture, with comprehensive improvements in text, image, video, and audio processing capabilities, and can directly generate videos with synchronized audio and visuals.
These technological upgrades are not only Alibaba's long-term investment in foundation models, but also a reflection of its focus on industrial applications and promoting the expansion of the large model ecosystem.
K-jie also obtained trial access at the first opportunity~ Next, let's take a look together at the actual test results.
01. The key to synchronized audio and visuals: cross-modal alignment
Wan2.5 provides two major functions: image generation and video generation,and supports generating videos from audio paired with prompts/images。
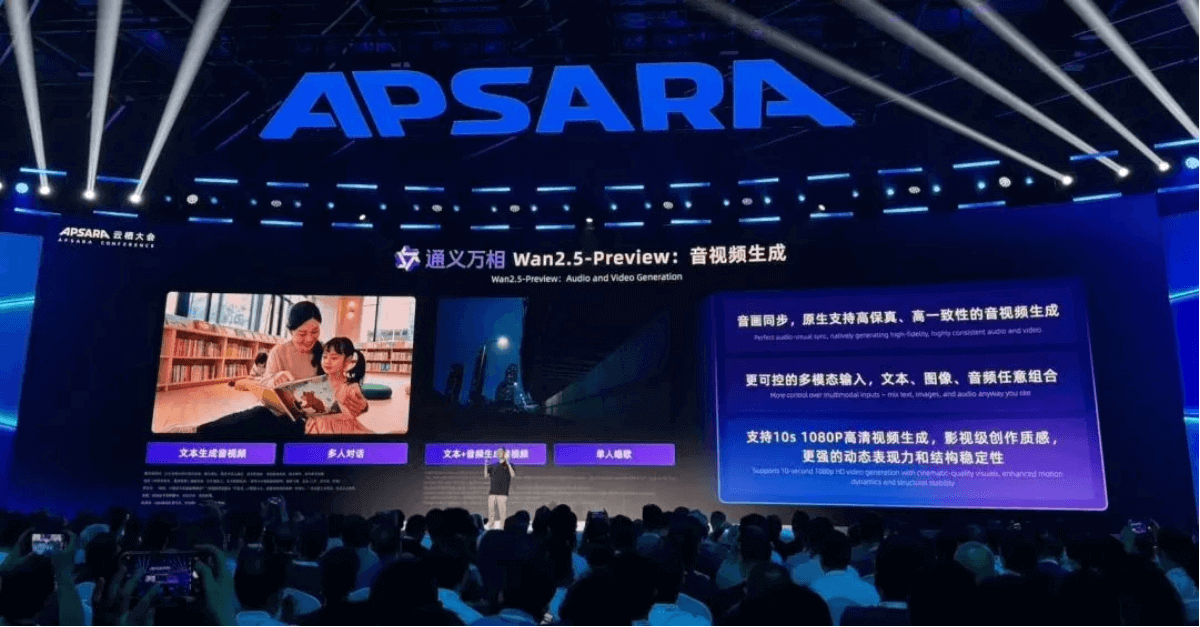
We only need to add descriptions of vocals, ambient sound effects, and background music on top of the prompts used in everyday text/image-to-video generation, and we can get a finished video with synchronized audio and visuals.
The maximum video generation duration is 10s, and it can generate high-definition videos at 1080p and 24fps.
Official website:https://tongyi.aliyun.com/wan/
Without further ado, let's first show a few actual test cases so everyone can get a feel:
case1 Variety show recording
prompt: At the recording site of a variety show, the stage is arranged in a living room style, with soft warm lighting, two sofas placed facing the audience, and drinks and snacks on the coffee table in the middle. A young male idol sits on the sofa, wearing fashionable casual clothes, holding a microphone in his hand, and says: "I won't say charming words, but the charming me is speaking right now." The live audience bursts into laughter, and the camera cuts to other guests, who laugh while clapping.
In this 5-second shot, Wan2.5's adherence to the prompt is very high, and the image details are handled quite well, such as the living room style, warm lighting, and the drinks and snacks on the coffee table.
The character's speaking expression and lip movements are very natural. Especially during the camera movement, the character even actively leans toward the guests, making it feel like the microphone should be handed over the next second...
case2 Outdoor photography
Upload a photo of a snail
prompt: On a stormy day, rain densely beats on the grass, making a muffled "rustling" sound, mixed with the light sound of splashing droplets, and the surrounding environment is open and humid.
Dense raindrops hit the snail's shell and gather into large droplets that flow down. Wan2.5's understanding of the real world is pretty good. Based on the scene in the image and the prompt, it generated matching ambient sound effects, and the consistency between sound and visuals is also very good.
case3 Concert
We upload a segment of song audio.
prompt: Close-up shot, a very beautiful female singer stands in the center of the concert stage singing affectionately. She wears an exquisite gown, her long hair draped over her shoulders, gently fluttering in the breeze, and appears even more moving under the stage lights. She grips the microphone tightly with both hands, her voice high and full, her emotions surging.
The video's lighting and colors are very good, especially the hair light, which is very lively and real. The character's lip movements in the footage also match the audio very well.
Wan2.5's audio-visual synchronization is not simply making a character's mouth move; it also adds many details, such as slight head swaying, neck muscles tensing when straining, and the shoulders contracting and rising with breathing. These details make the whole scene feel more alive, as if it were truly shot on location.
02. Wan2.5 vs. Veo3
case1 Food video
prompt: A female college student around 20 years old, sitting in a bustling snack street, picks up a small piece of braised pork with chopsticks, chews slowly, leans close to the camera, and says softly: "Delicious." Her voice is sweet and her tone is light. The background sound is the noisy bustle of people coming and going on the snack street.
Wan2.5 andVeo3The visual content both generated is quite good, but Veo3 seems to have encountered a BUG; the entire video has no sound.
case2 The evolution of television
prompt: Locked wide-angle shot, filming the same living room from the front, with the TV in the center of the frame and always kept in a centered composition. The image shows the evolution of television over several decades, from the black-and-white TVs of the 1950s, to the wooden cabinets of the 1970s, to the CRT monitors of the 1990s, to the flat-panel TVs of the 2000s, and finally the smart OLED TVs of the 2020s. The furniture, colors, and style also change with the times: retro 1970s, minimalist 1990s, modern 2000s, futuristic 2020s.
Lens: 35mm cinematic lens, clear details.
Sound effects: visual static, channel switching sounds, and remote control clicks synchronized with the era transitions.
Blend level: smooth transitions between eras
Wan2.5 follows the prompt much more closely: the television is always in the exact center of the frame, and it consistently uses a centered composition, making the theme more intuitive.
In terms of interior design style, the differences between eras in Wan2.5 are not very large; Veo3 does a bit better in this regard.
Both Wan2.5 and Veo3 show television styles from multiple eras, and both also add sound effects during the transitions.
03. Some sharing
In the past, video generation always had audio that did not match the visuals, and you still had to add voice, lip-sync, and background sound on different platforms. Now, a minimal prompt can generate a complete video with synchronized audio and visuals.
Wan2.5 makes creation directly "visualizable" and "audible." For short videos, virtual streamers, or even remote teaching, there is no longer any need to rely on complex post-production; AI can do it all with one click, greatly lowering the barrier to creation.
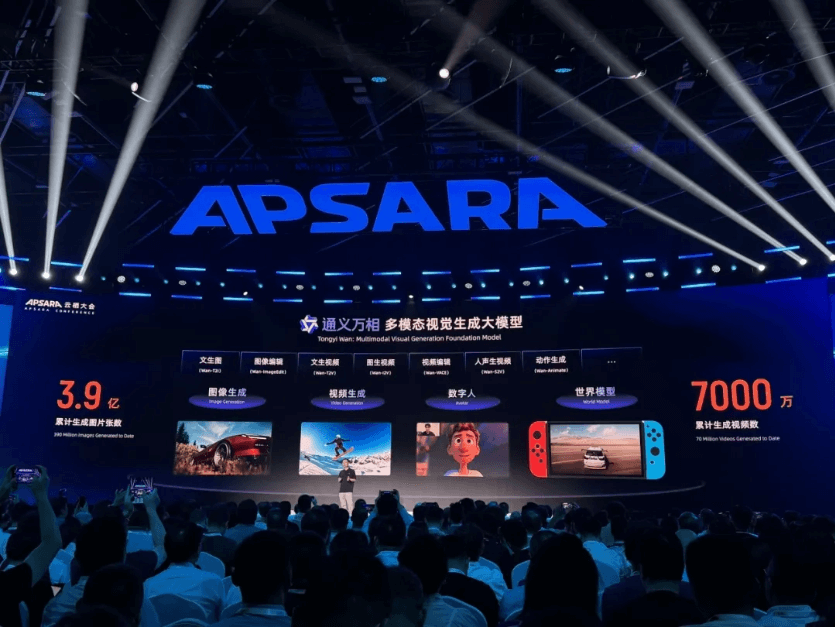
Wan2.5 can simultaneously align the rhythm of sound, the semantics of language, and the actions in the visuals. This is not just an evolution in video generation, but a key step toward the mature application of multimodal AI.
Advertising, education, film and television, and gaming all used to rely on manual voiceover and post-production, which was costly and time-consuming. Wan2.5 brings video generation up to the level of a production-grade tool, and low-cost, high-quality virtual content may soon explode in growth.
Original link:At the 2025 Yunqi Conference, Alibaba pulled off something big!