
What is 3DV-TON
3DV-TON (Textured 3D-Guided Consistent Video Try-on via Diffusion Models) is a video virtual try-on framework based on diffusion models, jointly launched by Alibaba DAMO Academy, Hupan Lab, and Zhejiang University.Virtual try-onframework, capable of solving the problem of poor generation results in existing methods when handling complex clothing patterns and diverse human poses. The framework is based on generating animatable textured 3D meshes as explicit frame-level guidance, ensuring that the generated try-on videos perform excellently in visual quality and temporal consistency. 3DV-TON introduces the high-resolution benchmark dataset HR-VVT, advancing research progress in video try-on technology.
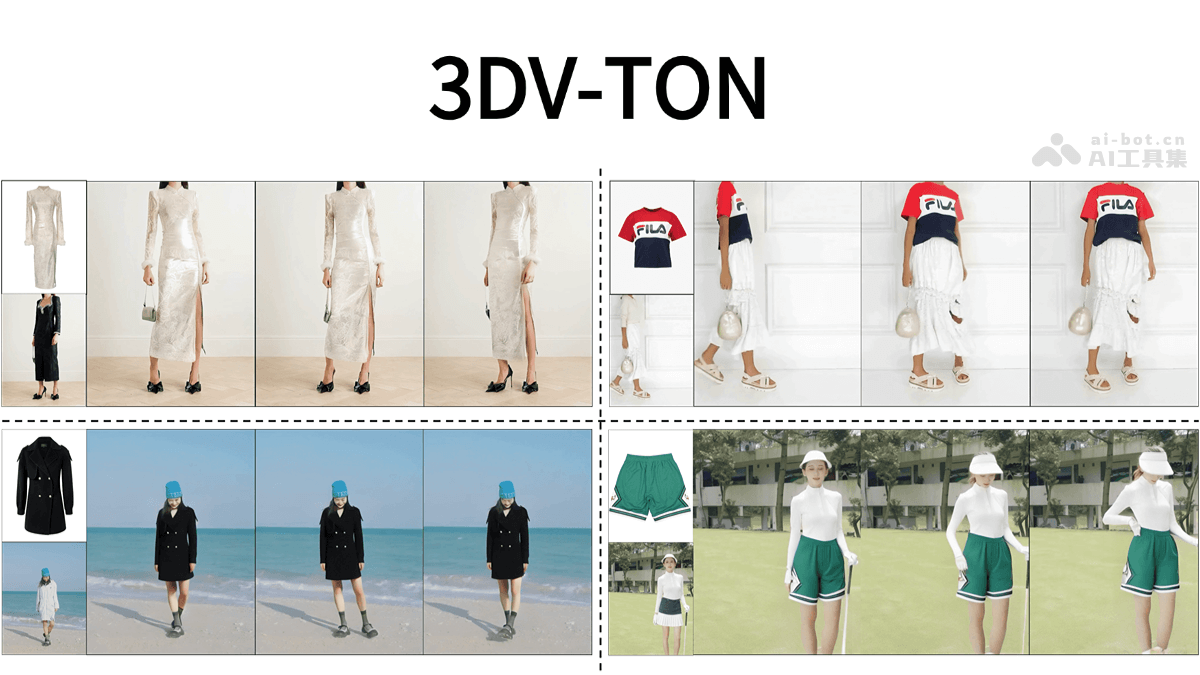
Main features of 3DV-TON
- High-fidelity visual effects: Accurately reproduces clothing details and generates realistic try-on effects.
- Temporal consistency: Ensures that clothing textures in the video maintain coherent motion across different frames, avoiding artifacts or deformation.
- Adaptation to complex scenarios: Supports handling diverse clothing types, complex human poses, and dynamic scenes.
- Provision of benchmark dataset: Introduces the high-resolution video try-on benchmark dataset HR-VVT, advancing research and evaluation in related fields.
Technical principles of 3DV-TON
- Textured 3D guidance: Single-image 3D reconstruction technology generates animatable textured 3D meshes. The 3D mesh is synchronized with the pose of the original video to provide explicit frame-level guidance for the diffusion model, ensuring consistency in appearance and motion of the generated try-on results.
- Dynamic 3D guidance pipeline: Select keyframes for initial 2D image try-on and reconstruct animatable textured 3D meshes. Optimize SMPL-X parameters to ensure precise alignment of the 3D mesh with the human pose.
- Rectangular mask strategy: Prevents clothing information leakage and avoids artifacts in dynamic human and clothing motion. Combines clothing images and try-on images as references to provide contextual information and enhance generation results.
- Diffusion model architecture: Based on Stable Diffusion, extends the UNet architecture to support pseudo-3D structures. Based on temporal module integration, it achieves realistic motion generation and reduces dependence on explicit optical flow or deformation operations.
- Training strategy: Combines image and video data for training, and balances image quality and temporal consistency based on randomly selected data types. Uses a classifier-free guidance (CFG) strategy to randomly omit certain conditional inputs, enhancing the model's robustness.
Project address of 3DV-TON
- Project official website:https://2y7c3.github.io/3DV-TON/
- arXiv technical paper:https://arxiv.org/pdf/2504.17414
Application scenarios of 3DV-TON
- Online shopping: Helps users virtually try on clothing, improves the shopping experience, and reduces returns.
- Fashion design: Quickly displays clothing design effects and assists design and marketing.
- Virtual fitting room: Saves try-on time and effort in physical stores.
- Film, television, and games: Assists character costume design and customization, improving production efficiency.
- Social media: Provides users with fun tools for creating and sharing try-on videos.