
What is 3DTown
3DTown is a framework launched by Columbia University in collaboration with Cybever AI and other institutions for generating 3D town scenes from a single top-down view. The framework is based on region-based generation and spatially aware 3D inpainting technology. It decomposes the input image into overlapping regions, generates 3D content for each region separately based on a pretrained 3D object generator, and fills in missing geometric structures based on a masked rectified flow inpainting process while maintaining structural continuity. 3DTown supports the generation of coherent 3D scenes with high geometric quality and texture fidelity, performs excellently in scene generation across multiple styles, and outperforms existing state-of-the-art methods.
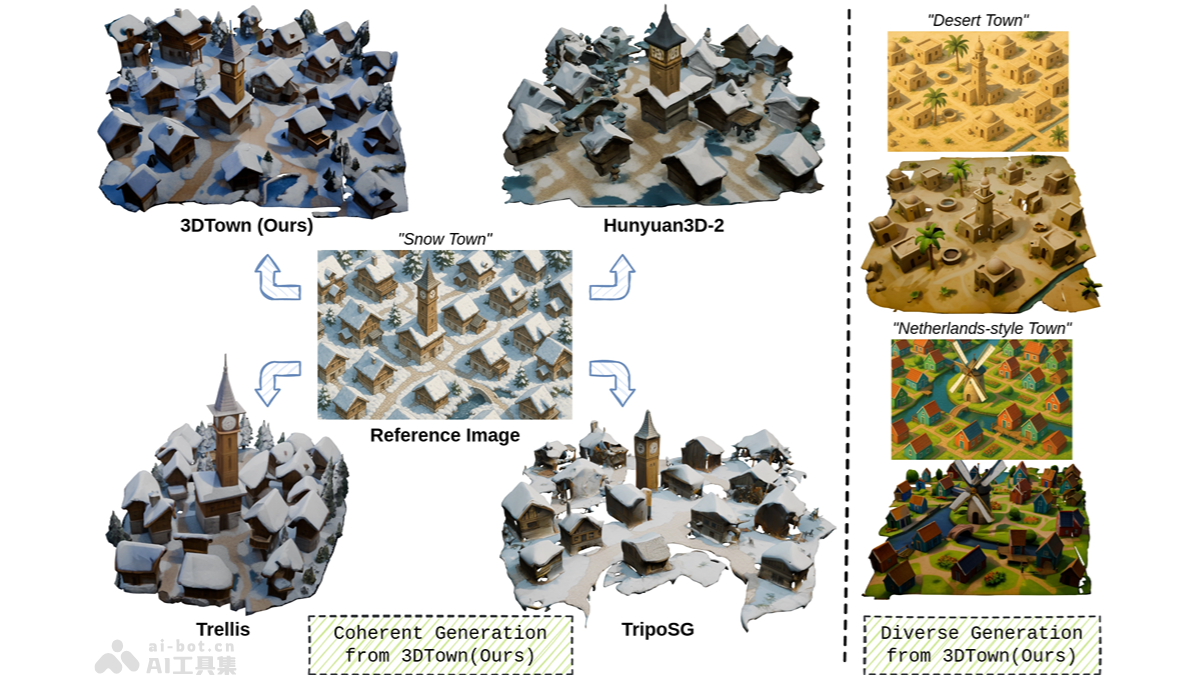
Main Features of 3DTown
- Generate diverse 3D scenes: Supports scene generation with different styles and layouts, such as "snow town," "desert town," and more.
- Maintain geometric and texture consistency: The generated 3D scenes are highly consistent with the input image in geometric structure and texture.
- Efficiently handle complex scenes: Can effectively handle complex scenes and avoid geometric distortion and layout hallucination.
Technical Principles of 3DTown
- Region-based generation: Decomposes the input image into overlapping regions, and each region independently generates 3D content. A pretrained 3D object generator is used to generate each region, improving local alignment and resolution. Based on region fusion, the generated regions are progressively merged into a coherent global 3D scene.
- Spatially aware 3D inpainting: Uses monocular depth estimation and landmark detection to initialize a rough 3D structure as a spatial prior. Based on Masked Rectified Flow technology, it fills in missing geometric structures while maintaining the continuity of known content. Based on a two-stage masked rectified flow pipeline, it generates sparse structures and structured latent representations to ensure global consistency.
- Structured latent representation: Constructs 3D scenes based on structured latent representations, including position indices and latent feature vectors. Uses a sparse structure generator and a structured latent generator to progressively generate the latent representation of the 3D scene.
- Modular design: Based on a modular design, it decomposes the complex 3D scene generation problem into multiple subproblems, each solved independently before integration.
3DTown Project Address
- Project official website:https://eric-ai-lab.github.io/3dtown.github.io/
- arXiv technical paper:https://arxiv.org/pdf/2505.15765
Application Scenarios of 3DTown
- Virtual world construction: Rapidly generates virtual towns or scenes, providing realistic environments for virtual reality (VR) and augmented reality (AR) applications.
- Game development: Provides game designers with an efficient tool to generate complex 3D game scenes from simple top-down views, saving time and cost.
- Robot simulation: Creates realistic 3D scenes for robot training, improving robots' navigation and interaction capabilities in complex environments.
- Digital content creation: Helps artists and designers quickly generate 3D scene prototypes, accelerating the creative process and improving work efficiency.
- Architecture and urban planning: Generates 3D architectural models and urban layouts from conceptual sketches, assisting planning and design work and facilitating proposal presentation and evaluation.